An offline preference pair does not show what happens when a policy generates its own training examples. This activity samples short completions, assigns an explicit token reward, and performs actual group-relative parameter updates. Keeping the old sample probabilities fixed lets the code compare the updated policy with the policy that produced the samples.
When you need this. You need to trace a sampling-and-update loop before interpreting a reinforcement-learning result. Inspect the generated tokens, their rewards and the old/current/reference roles separately; an increasing reward-token probability does not measure reasoning or useful answers.
An advantage describes a reward relative to other completions in the same group. This code subtracts the group mean and divides by its population standard deviation plus 1e-8. The same sequence advantage applies to each completion token. A current/old token-probability ratio enters a clipped surrogate; a sampled reference penalty is added separately. The DeepSeekMath paper, section 4.1, defines group-relative optimization. This lab implements a fixed-length mechanism experiment rather than its model-training recipe.
Each outer step samples a new group from the then-current policy and saves detached token log probabilities before any update. Two inner SGD steps reuse that fixed group and its old scores. Current log probabilities remain differentiable; old scores are detached and reference scores run without gradients. After the inner steps, the next group comes from the updated policy.
Download the complete lab and enter preference-policy-updates/. Create an isolated Python environment and install its pinned dependency with python -m pip install -r requirements.txt. The computation uses CPU tensors; no pretrained model download, GPU or paid service is needed. The PyTorch installation guide covers platform-specific installation choices. Another library version requires rerunning the checks.
1. Inspect what is actually rewarded
The prompt is [1,3]. Each of 16 completions contains 2 sampled tokens. The reward is 1 if the first generated token equals 6; otherwise 0. It is an authored syntactic rule, with no semantic interpretation of token 6. Sampling uses the policy’s softmax probabilities and the saved generator seed 47.
Inspect the first group’s completions and rewards in the raw trace. Its positive-reward count is 1. Every recorded reward can be recomputed directly from its generated first token; test_online_rewards_correspond_to_actual_generated_tokens checks that link.
2. Separate policy ratios from reference regularization
For each sampled token, the ratio is exp(current_logp - old_logp). The code takes the smaller of the unclipped advantage-weighted ratio and the ratio clipped to 1 ± clip, then negates the surrogate for minimization. With delta = reference_logp - current_logp, its sampled KL penalty is exp(delta) - delta - 1. This is a sampled penalty term, not a reported exact vocabulary-wide KL.
python run.py grpoThe saved loop samples 128 completions across 8 groups, with 2 updates per group. Clip is 0.2; KL coefficient is 0.04. Token 6’s next-token probability after the fixed prompt changes from 0.111481 to 0.129102. This is one seeded fixture result, not a semantic-quality score.
Read the complete implementation
"""DPO and online group-relative updates on a tiny synthetic-vocabulary LM.

This is an objective/mechanism experiment, not pretrained-model alignment.
"""
import copy
import json
import math
from pathlib import Path
import torch
import torch.nn.functional as F
import decoder

HERE = Path(__file__).resolve().parent
PAIRS = [{'prompt': [1, 3], 'chosen': [6, 2], 'rejected': [4, 2]},
         {'prompt': [2, 5], 'chosen': [6, 2], 'rejected': [7, 2]}]


def policy():
    return decoder.tensors(decoder.params())


def frozen(parameters):
    return {key: value.detach().clone() for key, value in parameters.items()}


def token_logps(parameters, prompt, completion):
    if not isinstance(prompt, list) or not isinstance(completion, list) or not prompt or not completion:
        raise ValueError('prompt and completion must be nonempty')
    ids = prompt + completion[:-1]
    decoder.inputs(parameters, ids, [0] * len(ids))
    decoder.inputs(parameters, completion, [0] * len(completion))
    logits, _ = decoder.forward(parameters, ids, [0] * len(ids))
    selected = logits[len(prompt)-1:].log_softmax(-1)
    return selected.gather(1, torch.tensor(completion).unsqueeze(1)).squeeze(1)


def dpo_loss(parameters, reference, pairs, beta=0.3):
    if not math.isfinite(beta) or beta <= 0 or not pairs:
        raise ValueError('positive beta and preference pairs required')
    losses = []
    for pair in pairs:
        if not isinstance(pair, dict) or set(pair) != {'prompt', 'chosen', 'rejected'} or pair['chosen'] == pair['rejected']:
            raise ValueError('distinct chosen and rejected completions required')
        prompt, chosen, rejected = (pair[key] for key in ('prompt', 'chosen', 'rejected'))
        margin = token_logps(parameters, prompt, chosen).sum() - token_logps(parameters, prompt, rejected).sum()
        with torch.no_grad():
            ref_margin = token_logps(reference, prompt, chosen).sum() - token_logps(reference, prompt, rejected).sum()
        losses.append(-F.logsigmoid(beta * (margin - ref_margin)))
    return torch.stack(losses).mean()


def sample(parameters, prompt, count, length, generator):
    if type(count) is not int or count < 2 or type(length) is not int or length < 1:
        raise ValueError('group size >=2 and positive completion length required')
    completions = []
    with torch.no_grad():
        for _ in range(count):
            generated = []
            for _ in range(length):
                ids = prompt + generated
                decoder.inputs(parameters, ids, [0] * len(ids))
                logits, _ = decoder.forward(parameters, ids, [0] * len(ids))
                token = torch.multinomial(logits[-1].softmax(-1), 1, generator=generator).item()
                generated.append(token)
            completions.append(generated)
    return completions


def advantages(rewards):
    values = torch.tensor(rewards, dtype=torch.float64)
    if values.ndim != 1 or len(values) < 2 or not torch.isfinite(values).all():
        raise ValueError('finite reward group with at least two members required')
    std = values.std(unbiased=False)
    if std.item() == 0:
        return torch.zeros_like(values)
    return (values - values.mean()) / (std + 1e-8)


def grpo_loss(parameters, reference, old_logps, prompt, completions, rewards, clip=0.2, beta=0.04):
    if not 0 < clip < 1 or not math.isfinite(beta) or beta < 0:
        raise ValueError('clip in (0,1) and nonnegative finite KL coefficient required')
    if not (len(completions) == len(rewards) == len(old_logps)) or len({len(c) for c in completions}) != 1:
        raise ValueError('aligned equal-length completion group required')
    if any(not isinstance(old, torch.Tensor) or old.shape != (len(completion),) or not torch.isfinite(old).all() for old, completion in zip(old_logps, completions)):
        raise ValueError('old-policy token log-probabilities must align with completions')
    advantage = advantages(rewards)
    losses = []
    for i, completion in enumerate(completions):
        current = token_logps(parameters, prompt, completion)
        ratio = (current - old_logps[i].detach()).exp()
        with torch.no_grad():
            ref = token_logps(reference, prompt, completion)
        delta = ref - current
        kl = delta.exp() - delta - 1
        surrogate = torch.minimum(ratio * advantage[i], ratio.clamp(1-clip, 1+clip) * advantage[i])
        losses.append((-surrogate + beta * kl).mean())
    return torch.stack(losses).mean()


def run_dpo():
    parameters = policy(); reference = frozen(parameters)
    optimizer = torch.optim.SGD(parameters.values(), lr=0.1)
    before = dpo_loss(parameters, reference, PAIRS).item()
    history = []
    for _ in range(30):
        optimizer.zero_grad();loss = dpo_loss(parameters, reference, PAIRS)
        loss.backward();optimizer.step();history.append(loss.item())
    after = dpo_loss(parameters, reference, PAIRS).item()
    return {'mode': 'fresh CPU parameter updates on a tiny synthetic-vocabulary language model',
            'method': 'DPO sigmoid loss; frozen reference; completion log-probability sums',
            'pairs': PAIRS, 'beta': 0.3, 'steps': len(history), 'learning_rate': 0.1,
            'loss_before': before, 'loss_after': after, 'loss_history': history,
            'reference_has_gradients': any(t.grad is not None for t in reference.values()),
            'scope': 'Authored token preferences, not human annotation or pretrained-model alignment.'}


def run_grpo():
    parameters = policy(); reference = frozen(parameters)
    optimizer = torch.optim.SGD(parameters.values(), lr=0.02)
    generator = torch.Generator().manual_seed(47)
    prompt = [1, 3]; trace = []
    def desired_probability():
        with torch.no_grad():
            logits, _ = decoder.forward(parameters, prompt, [0] * len(prompt))
            return logits[-1].softmax(-1)[6].item()
    before = desired_probability()
    for step in range(8):
        completions = sample(parameters, prompt, 16, 2, generator)
        # Authored syntactic reward: first generated token equals token 6.
        rewards = [float(completion[0] == 6) for completion in completions]
        old = [token_logps(parameters, prompt, completion).detach() for completion in completions]
        a = advantages(rewards)
        losses = []
        for _ in range(2):
            optimizer.zero_grad();loss = grpo_loss(parameters, reference, old, prompt, completions, rewards)
            loss.backward();optimizer.step();losses.append(loss.item())
        trace.append({'step': step, 'completions': completions, 'rewards': rewards,
                      'advantages': a.tolist(), 'losses': losses, 'zero_variance': bool(a.eq(0).all())})
    return {'mode': 'fresh online CPU sampling and parameter updates on a tiny synthetic-vocabulary LM',
            'method': 'fixed-length token-level clipped group-relative objective with sampled KL penalty',
            'prompt': prompt, 'seed': 47, 'group_size': 16, 'completion_length': 2,
            'groups': len(trace), 'inner_updates': 2, 'clip': 0.2, 'kl_beta': 0.04,
            'reward': '1 if the first generated token equals 6; otherwise 0',
            'desired_token_probability_before': before, 'desired_token_probability_after': desired_probability(),
            'sampled_completions': sum(len(group['completions']) for group in trace), 'trace': trace,
'scope': 'No semantic quality, human preference, reasoning or held-out capability claim.'}{
"mode": "fresh online CPU sampling and parameter updates on a tiny synthetic-vocabulary LM",
"method": "fixed-length token-level clipped group-relative objective with sampled KL penalty",
"prompt": [
1,
3
],
"seed": 47,
"group_size": 16,
"completion_length": 2,
"groups": 8,
"inner_updates": 2,
"clip": 0.2,
"kl_beta": 0.04,
"reward": "1 if the first generated token equals 6; otherwise 0",
"desired_token_probability_before": 0.11148078965736573,
"desired_token_probability_after": 0.1291018612493509,
"sampled_completions": 128,
"trace": [
{
"step": 0,
"completions": [
[
7,
0
],
[
1,
4
],
[
4,
7
],
[
8,
3
],
[
2,
3
],
[
2,
7
],
[
2,
7
],
[
0,
8
],
[
1,
7
],
[
6,
5
],
[
8,
2
],
[
5,
4
],
[
1,
5
],
[
7,
1
],
[
1,
5
],
[
8,
4
]
],
"rewards": [
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
1.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0
],
"advantages": [
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
3.8729831862074233,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949
],
"losses": [
-5.551115123125783e-17,
-0.003930382077496852
],
"zero_variance": false
},
{
"step": 1,
"completions": [
[
5,
1
],
[
5,
3
],
[
5,
2
],
[
1,
4
],
[
6,
6
],
[
2,
8
],
[
4,
4
],
[
6,
2
],
[
6,
6
],
[
0,
8
],
[
0,
4
],
[
6,
5
],
[
0,
8
],
[
6,
3
],
[
1,
1
],
[
1,
6
]
],
"rewards": [
0.0,
0.0,
0.0,
0.0,
1.0,
0.0,
0.0,
1.0,
1.0,
0.0,
0.0,
1.0,
0.0,
1.0,
0.0,
0.0
],
"advantages": [
-0.6741998479177879,
-0.6741998479177879,
-0.6741998479177879,
-0.6741998479177879,
1.4832396654191333,
-0.6741998479177879,
-0.6741998479177879,
1.4832396654191333,
1.4832396654191333,
-0.6741998479177879,
-0.6741998479177879,
1.4832396654191333,
-0.6741998479177879,
1.4832396654191333,
-0.6741998479177879,
-0.6741998479177879
],
"losses": [
4.298648638087488e-06,
-0.013618458296495072
],
"zero_variance": false
},
{
"step": 2,
"completions": [
[
6,
0
],
[
3,
7
],
[
0,
4
],
[
3,
7
],
[
8,
0
],
[
5,
4
],
[
7,
3
],
[
1,
5
],
[
5,
2
],
[
3,
0
],
[
7,
1
],
[
6,
8
],
[
4,
1
],
[
4,
2
],
[
7,
7
],
[
1,
4
]
],
"rewards": [
1.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
1.0,
0.0,
0.0,
0.0,
0.0
],
"advantages": [
2.645751231064593,
-0.3779644615806561,
-0.3779644615806561,
-0.3779644615806561,
-0.3779644615806561,
-0.3779644615806561,
-0.3779644615806561,
-0.3779644615806561,
-0.3779644615806561,
-0.3779644615806561,
-0.3779644615806561,
2.645751231064593,
-0.3779644615806561,
-0.3779644615806561,
-0.3779644615806561,
-0.3779644615806561
],
"losses": [
1.8937726466543292e-05,
-0.0052481505746524645
],
"zero_variance": false
},
{
"step": 3,
"completions": [
[
8,
2
],
[
2,
7
],
[
0,
4
],
[
4,
0
],
[
2,
1
],
[
7,
7
],
[
8,
1
],
[
3,
4
],
[
2,
6
],
[
3,
1
],
[
1,
1
],
[
1,
5
],
[
1,
3
],
[
5,
1
],
[
8,
4
],
[
2,
2
]
],
"rewards": [
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0
],
"advantages": [
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0
],
"losses": [
1.7504131772867747e-05,
1.7477067288182437e-05
],
"zero_variance": true
},
{
"step": 4,
"completions": [
[
1,
5
],
[
1,
3
],
[
5,
0
],
[
0,
2
],
[
2,
6
],
[
2,
2
],
[
4,
1
],
[
5,
0
],
[
1,
8
],
[
1,
3
],
[
5,
4
],
[
8,
1
],
[
5,
6
],
[
4,
7
],
[
6,
0
],
[
8,
0
]
],
"rewards": [
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
1.0,
0.0
],
"advantages": [
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
-0.2581988790804949,
3.8729831862074233,
-0.2581988790804949
],
"losses": [
3.07142974115826e-05,
-0.004061774007876218
],
"zero_variance": false
},
{
"step": 5,
"completions": [
[
5,
6
],
[
2,
2
],
[
2,
1
],
[
7,
1
],
[
7,
4
],
[
5,
1
],
[
8,
3
],
[
1,
1
],
[
4,
6
],
[
7,
0
],
[
5,
3
],
[
5,
8
],
[
0,
2
],
[
3,
3
],
[
1,
6
],
[
7,
0
]
],
"rewards": [
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0
],
"advantages": [
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0
],
"losses": [
2.3184429881991095e-05,
2.314783456622477e-05
],
"zero_variance": true
},
{
"step": 6,
"completions": [
[
4,
4
],
[
4,
8
],
[
2,
8
],
[
2,
4
],
[
1,
8
],
[
5,
3
],
[
4,
6
],
[
7,
5
],
[
5,
7
],
[
4,
5
],
[
5,
2
],
[
0,
6
],
[
5,
7
],
[
7,
8
],
[
7,
3
],
[
2,
0
]
],
"rewards": [
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0
],
"advantages": [
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0
],
"losses": [
1.3303339240217648e-05,
1.3288557138457224e-05
],
"zero_variance": true
},
{
"step": 7,
"completions": [
[
7,
3
],
[
8,
2
],
[
8,
1
],
[
3,
3
],
[
5,
5
],
[
8,
2
],
[
5,
7
],
[
5,
2
],
[
3,
1
],
[
2,
2
],
[
4,
3
],
[
2,
1
],
[
8,
2
],
[
0,
8
],
[
5,
1
],
[
4,
4
]
],
"rewards": [
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0
],
"advantages": [
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0,
0.0
],
"losses": [
7.528826018083634e-06,
7.523662128849917e-06
],
"zero_variance": true
}
],
"scope": "No semantic quality, human preference, reasoning or held-out capability claim.",
"refusal": "finite reward group with at least two members required",
"command": [
"python",
"run.py",
"grpo",
"--record"
],
"exit_status": 0,
"environment": {
"python": "3.12.8",
"torch": "2.14.1",
"platform": "macOS-27.0.1-arm64-arm-64bit"
},
"sources": {
"updates.py": "471ac4ec96c3b092c0c7845a2f812d50dfaac4619fcc2a4bac19c8bd41992f0e",
"decoder.py": "5706ca21af551b17ee54ca00f5a6011981b327e03b1e880b6712c06dd7d1c39a",
"vendor/model.py": "0d3d469afd5f35ef19b04e0b0587143c39f8fbca37d6154e6435c4ed4e8b80fc",
"run.py": "bb3708aaf674c9cd55bd1a21276fb4d4a40e4cd4d15b239f1f994803142d50ce",
"test_updates.py": "bf71137ae859b1a405941645cdb0db4378fcf55478c548364570778d52186552"
}
}
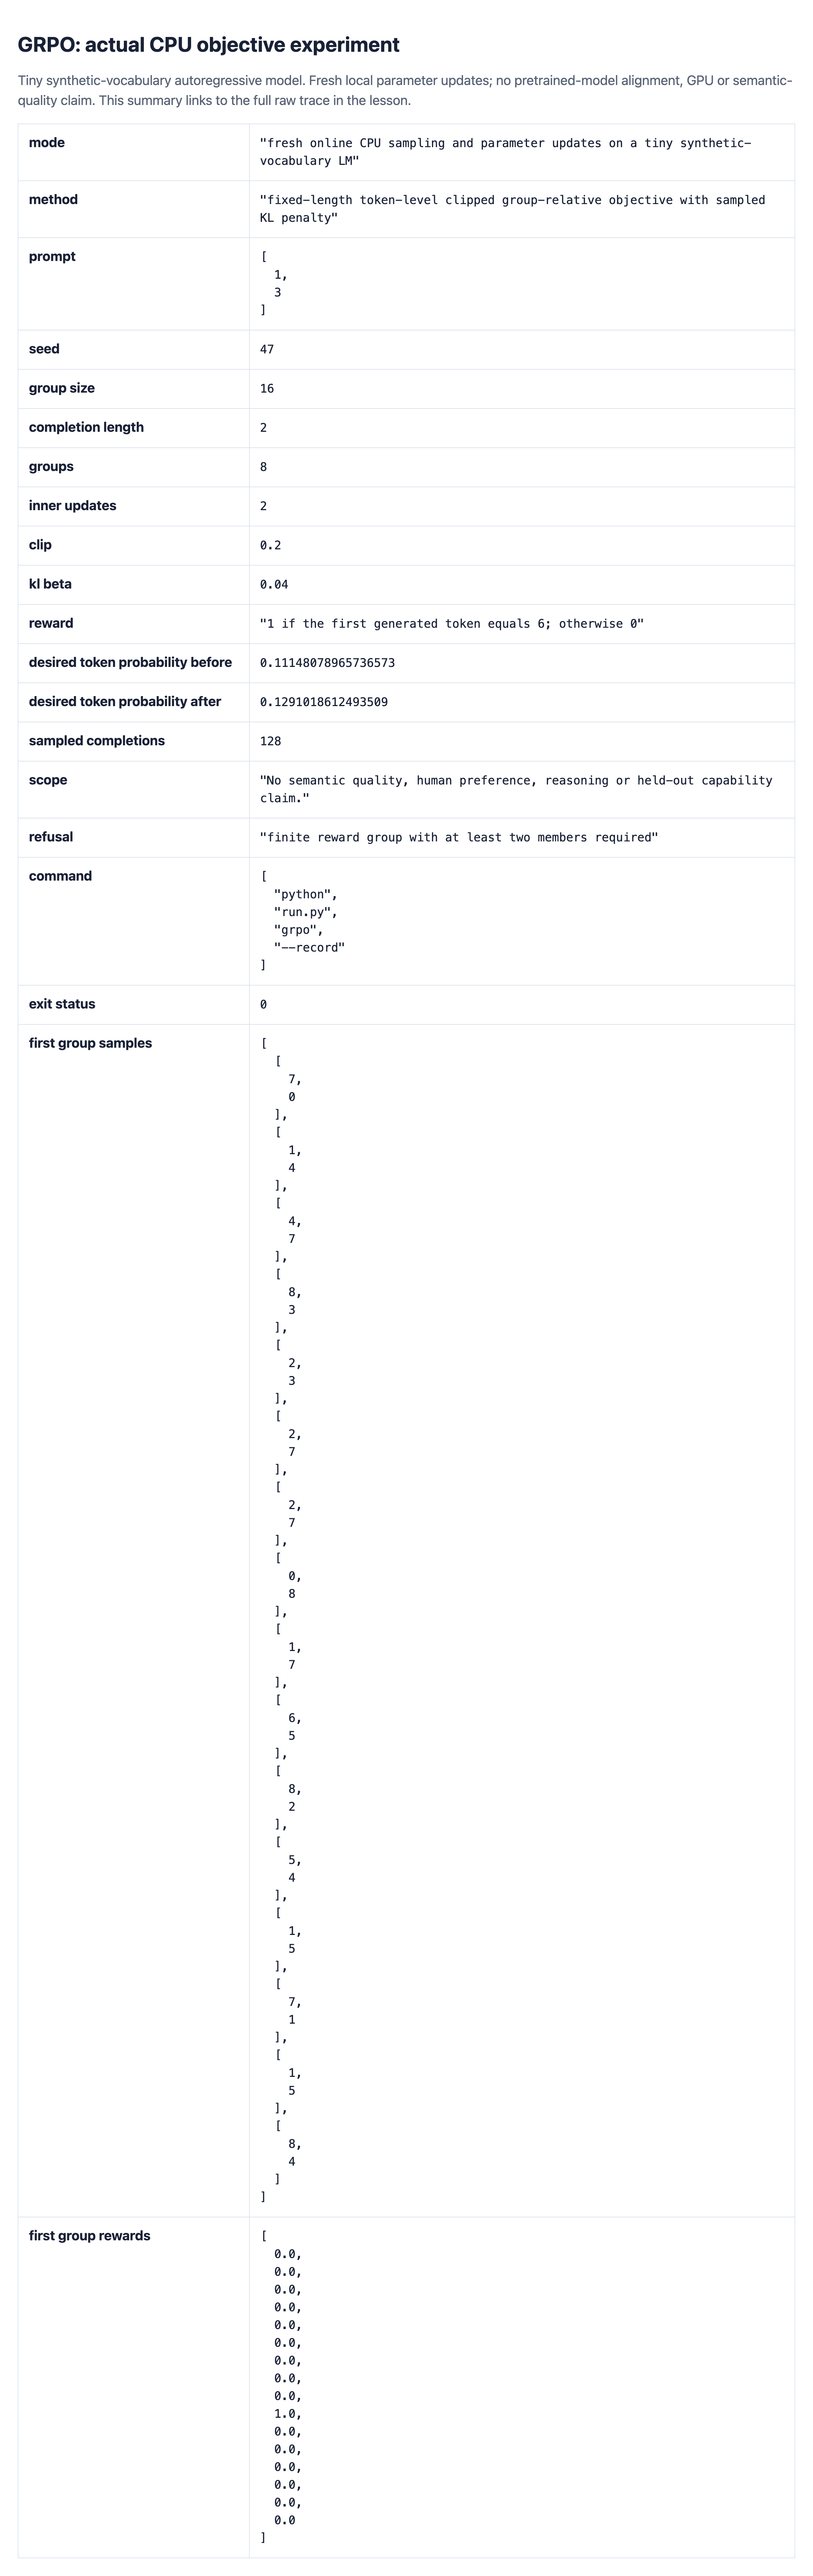
run.py grpo performs new local computation and leaves saved files unchanged. --record deliberately replaces this stage’s results and report. The raw record retains the command, exit status, runtime and implementation hashes.
Failure cases
| Boundary checked | Required behavior |
|---|---|
| Zero-variance rewards | Return zero reward advantages for an equal-reward group; the separate KL contribution may remain. |
| Invalid group alignment or clipping | Refuse mismatched groups and invalid clip bounds before computing a surrogate. |
| Invalid sampling group size | Refuse a sampling group with fewer than two completions. |
Every reward in a group is equal. The saved run has 4 such groups. Their reward advantages are zero. That removes the reward-surrogate contribution, but the KL term can still update a policy that differs from its reference. test_group_advantages_center_and_handle_zero_variance checks centering and the zero-advantage boundary.
Old scores do not align with generated tokens. test_grpo_alignment_and_invalid_clipping_refused checks inconsistent group sizes and invalid clipping bounds. Recomputing old scores after each update would change the probability-ratio baseline; keep the detached scores captured before the inner loop.
The sampling group is too small. test_sampling_uses_policy_and_preserves_fixed_lengths refuses a group size below two and checks the generated completion lengths. A group-relative comparison needs more than one completion.
A reward is nonfinite. The recorded refusal is finite reward group with at least two members required. Replace the invalid reward source rather than allowing NaN to enter advantage normalization. Run python -m unittest -v test_updates.py to exercise this boundary and actual sampling checks.
In a separate copy, make every reward equal and distinguish the zero reward gradient from any remaining reference penalty. Explain why neither a low surrogate loss nor more token-6 samples establishes useful text generation.
Interpret the result at its actual scope
The model is freshly initialized on a synthetic vocabulary. Completions have fixed lengths, so the implementation averages over tokens and then groups without padding or EOS masks. Variable-length completion masking, a learned reward model, pretrained-policy alignment and capability evaluation require additional work. No GPU or paid model service is involved.
Check your understanding
Read the explanation
A policy different from its reference can receive a KL gradient even when the reward surrogate is zero.
References
Primary sources checked October 24, 2026. The saved local execution, rather than the cited research results, supplies the measurements above.