The first labels to arrive can describe a different subset from the eventual population. Treating the rest as negative outcomes gives an early accuracy number that answers the wrong question. A retraining decision needs coverage and data checks alongside ready-label quality.
When you need this. Use an identity-based outcome join when labels become available after predictions and evaluation coverage changes over time.
Each prediction has its own identity, recorded label and prediction time. A finalized outcome may become usable only after the declared five-tick horizon and its ready_at timestamp. Coverage divides ready labels by all predictions eligible at the assembly cutoff. Accuracy uses only ready labels; it must be reported with that smaller denominator.
1. Follow the decision boundary
outcomes() requires one model cohort, checks unique identities, refuses unknown labels and premature finalization, then joins by ID. It preserves pending and missing counts separately. action() first checks data failures, then coverage, then ready-label quality. An authored review can permit preparation of a retraining review; this function never starts training.
The lab reuses an exact copy of the recorded Rice predictor, bundle and dataset from registry and serving. It performs no training and uses no cloud service. Monitoring fixtures are explicitly authored; the rollout parameter variant is labeled in the result. Keep the complete extracted mlops-rollout-monitoring/ directory together; Python’s standard library is sufficient.
Read the implementation for this activity
"""Compute independent signals and delayed-label coverage from authored fixtures."""
import math
from predictor import CONTRACT,baseline

def integer(v):
    if type(v) is not int or v<0:raise ValueError('nonnegative integer clock required')
    return v

def unique(rows):
    if not isinstance(rows,list) or any(not isinstance(r,dict) or not isinstance(r.get('id'),str) or not 1<=len(r['id'])<=80 for r in rows):
        raise ValueError('records need bounded string identities')
    ids=[r['id'] for r in rows]
    if len(ids)!=len(set(ids)):raise ValueError('duplicate event identity')

def signals(events,reference,now,max_age=15,cutpoint=12500):
    integer(now);integer(max_age);unique(events)
    if not reference or any(type(v) not in (int,float) or not math.isfinite(v) for v in reference):
        raise ValueError('finite nonempty reference required')
    counts={'schema_invalid':0,'unavailable':0,'stale':0,'fresh':0};areas=[]
    for event in events:
        try:
            if set(event)!={'id','feature_at','available_at','contract','features'}:raise ValueError('schema')
            feature_at=integer(event['feature_at']);available=integer(event['available_at'])
            if available<feature_at or event['contract']!=CONTRACT:raise ValueError('schema')
            values=event['features']
            if not isinstance(values,dict) or set(values)!=set(baseline.FEATURES):raise ValueError('schema')
            if any(type(v) not in (int,float) or not math.isfinite(v) for v in values.values()):raise ValueError('schema')
        except (ValueError,TypeError,OverflowError):counts['schema_invalid']+=1;continue
        if feature_at>now or available>now:counts['unavailable']+=1
        elif now-feature_at>max_age:counts['stale']+=1
        else:counts['fresh']+=1;areas.append(values['area'])
    reference_share=sum(v<=cutpoint for v in reference)/len(reference)
    distance=abs(sum(v<=cutpoint for v in areas)/len(areas)-reference_share) if len(areas)>=4 else None
    return {'events':len(events),'counts':counts,'distribution':{'feature':'area','cutpoint':cutpoint,
            'reference_rows':len(reference),'eligible_rows':len(areas),'minimum_rows':4,
            'reference_low_share':reference_share,'absolute_share_difference':distance,
            'threshold':0.5,'alert':distance>=0.5 if distance is not None else None}}

def outcomes(predictions,labels,as_of):
    integer(as_of);unique(predictions);unique(labels)
    expected={p['id']:p for p in predictions};by_id={r['id']:r for r in labels}
    if not set(by_id)<=set(expected):raise ValueError('unknown label identity')
    for p in predictions:
        if set(p)!={'id','predicted_at','model','contract','label'} or not isinstance(p['model'],str) or not p['model']:raise ValueError('prediction schema')
        integer(p['predicted_at'])
        if p['label'] not in baseline.LABELS or p['contract']!=CONTRACT:raise ValueError('prediction contract')
    if len({p['model'] for p in predictions})>1:raise ValueError('select one model cohort before joining outcomes')
    for row in labels:
        if set(row)!={'id','ready_at','label'}:raise ValueError('label schema')
        ready=integer(row['ready_at']);p=expected[row['id']]
        if row['label'] not in baseline.LABELS or ready<p['predicted_at']+5:raise ValueError('label not finalized after horizon')
    eligible=[p for p in predictions if p['predicted_at']<=as_of]
    ready=[p for p in eligible if p['id'] in by_id and by_id[p['id']]['ready_at']<=as_of]
    correct=sum(p['label']==by_id[p['id']]['label'] for p in ready)
    return {'as_of':as_of,'eligible_predictions':len(eligible),'ready_labels':len(ready),
            'pending':sum(p['id'] in by_id and by_id[p['id']]['ready_at']>as_of for p in eligible),
            'missing':sum(p['id'] not in by_id for p in eligible),'correct':correct,
            'coverage':len(ready)/len(eligible) if eligible else None,
            'accuracy_on_ready':correct/len(ready) if ready else None,
            'ready_prediction_ids':[p['id'] for p in ready]}

def action(signal,quality,review):
    # This explicit teaching policy selects a review action; it never starts training.
    if any(signal['counts'][key] for key in ('schema_invalid','stale','unavailable')):return 'investigate_data'
    if quality['coverage'] is None or quality['coverage']<0.75:return 'wait_for_labels'
    if quality['accuracy_on_ready'] is not None and quality['accuracy_on_ready']<0.75:
        if review=={'data_issue_ruled_out':True,'persistent_failure_reviewed':True,'new_labels_reviewed':True}:
            return 'prepare_retraining_review'
        return 'investigate_quality'
    return 'monitor_distribution' if signal['distribution']['alert'] else 'continue_monitoring'
Download the complete lab, extract it and open mlops-rollout-monitoring/. The candidate is an intentionally altered parameter fixture used to demonstrate routing. It has not been approved by the earlier quality gate for a real release.
2. Run the focused activity
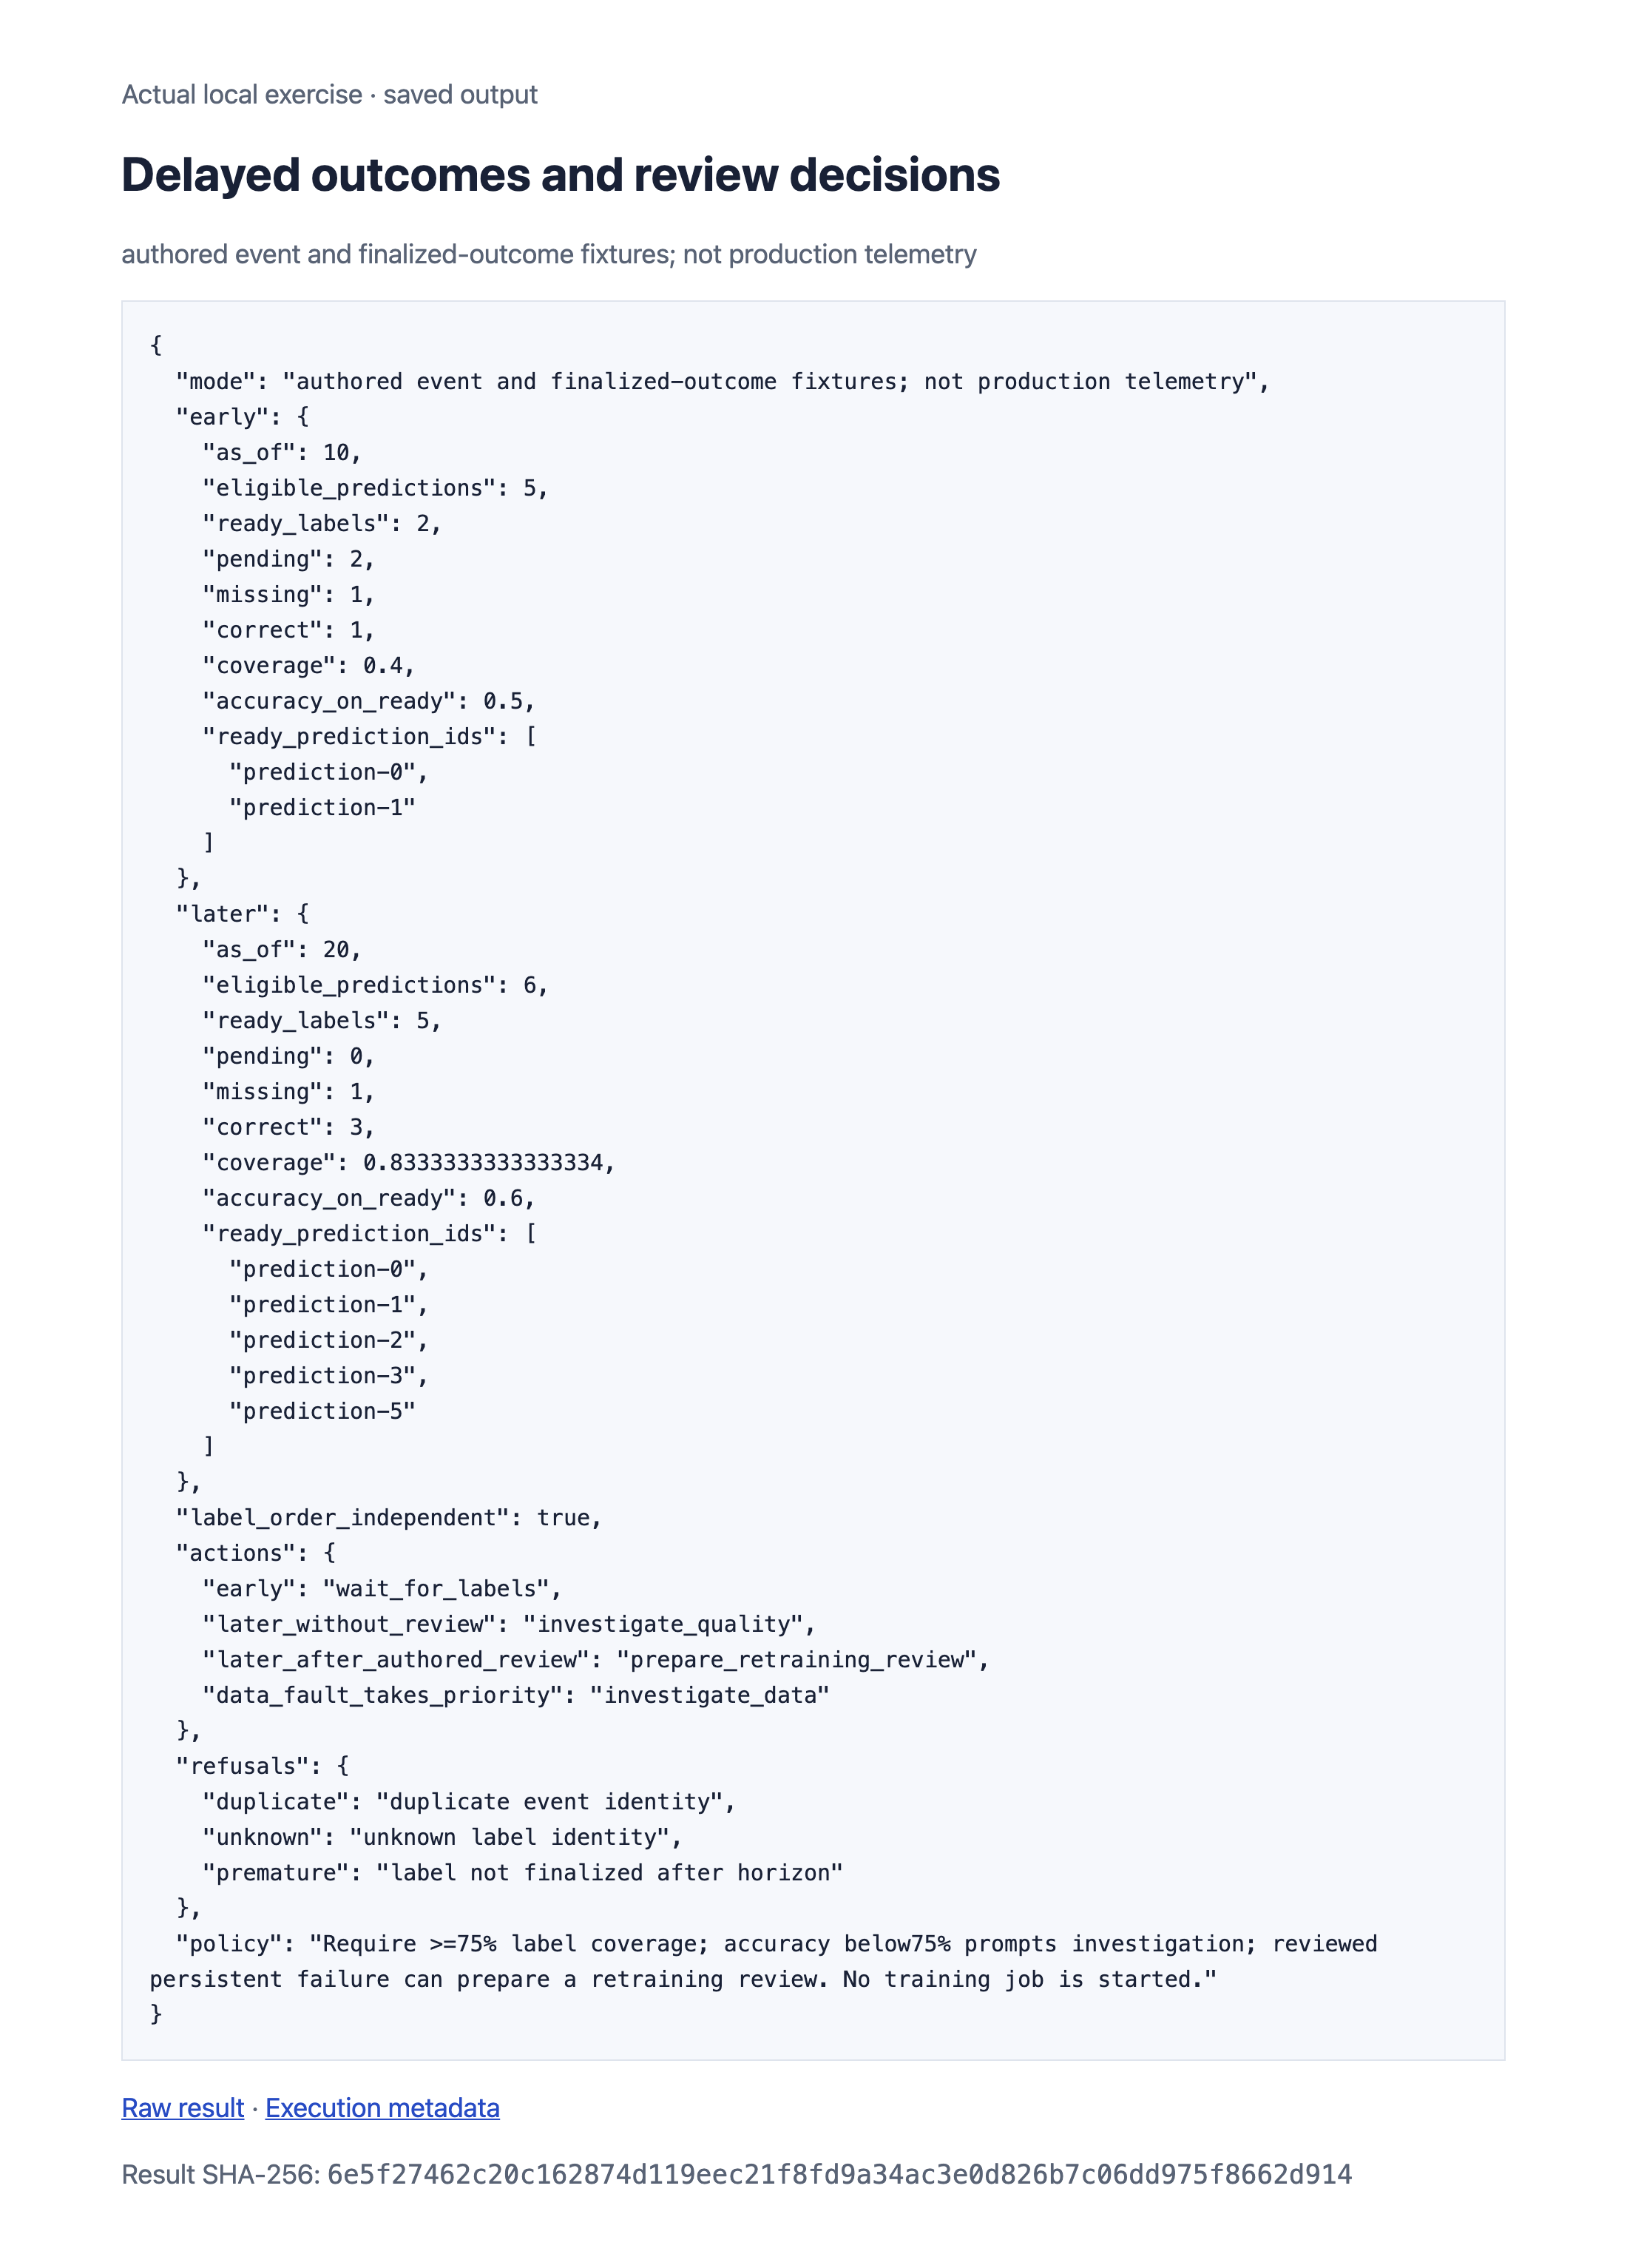
Run python exercise.py delayed. At cutoff 10, five predictions are eligible but only two labels are ready: coverage is 2/5 and ready-label accuracy is 1/2. The selected action is wait_for_labels. At cutoff 20, six predictions are eligible and five labels ready; three are correct. One label remains missing. Coverage 5/6 passes the exercise threshold, while accuracy 3/5 prompts investigate_quality.
python exercise.py delayed{
"mode": "authored event and finalized-outcome fixtures; not production telemetry",
"early": {
"as_of": 10,
"eligible_predictions": 5,
"ready_labels": 2,
"pending": 2,
"missing": 1,
"correct": 1,
"coverage": 0.4,
"accuracy_on_ready": 0.5,
"ready_prediction_ids": [
"prediction-0",
"prediction-1"
]
},
"later": {
"as_of": 20,
"eligible_predictions": 6,
"ready_labels": 5,
"pending": 0,
"missing": 1,
"correct": 3,
"coverage": 0.8333333333333334,
"accuracy_on_ready": 0.6,
"ready_prediction_ids": [
"prediction-0",
"prediction-1",
"prediction-2",
"prediction-3",
"prediction-5"
]
},
"label_order_independent": true,
"actions": {
"early": "wait_for_labels",
"later_without_review": "investigate_quality",
"later_after_authored_review": "prepare_retraining_review",
"data_fault_takes_priority": "investigate_data"
},
"refusals": {
"duplicate": "duplicate event identity",
"unknown": "unknown label identity",
"premature": "label not finalized after horizon"
},
"policy": "Require >=75% label coverage; accuracy below75% prompts investigation; reviewed persistent failure can prepare a retraining review. No training job is started."
}The raw result, execution metadata and locally generated actual-output report retain the computed counts and source identities. Opening the report does not repeat execution. --record deliberately replaces that stage’s saved files; ordinary execution leaves them unchanged.

3. Inspect refusals before acting
| Failure condition | Required behavior |
|---|---|
| Missing outcomes become negatives | Missing and pending labels remain outside the observed-accuracy denominator, with their coverage counts retained. |
| Invalid finalized labels | Refuse duplicate, unknown and prematurely finalized outcome labels before joining. |
| Insufficient or unreviewed retraining decision | Require sufficient label coverage and explicit review before preparing a retraining review; never start training automatically. |
Duplicate labels, labels for unknown prediction IDs and finalization before the outcome horizon all refuse the join. Reversing label order leaves the result unchanged. test_duplicate_unknown_premature_labels_refused and test_delayed_labels_do_not_become_negative_outcomes protect these rules. test_empty_cohort_has_no_accuracy_or_coverage keeps empty denominators undefined.
python -m unittest -v test_continuation.pyChange only a late label’s readiness timestamp in a temporary copy. Predict which cutoff gains coverage and which historical predictions remain unchanged. Explain why a retraining review still needs a new training run and separate candidate evaluation before any release.
How the result should guide the next step
The review policy uses 75% coverage and 75% accuracy as explicit teaching choices, not production thresholds. The supplied review says data issues were ruled out, persistent failure reviewed and new labels reviewed; those are authored inputs, not a completed real investigation. With that input the action becomes prepare_retraining_review. A schema fault still takes priority. Missing labels can bias the ready subset even when coverage crosses a chosen threshold.
Check your understanding
Read the explanation
This fixture chooses wait_for_labels until its coverage requirement is met. The ready subset alone does not satisfy that rule.
References
Official primary sources checked October 24, 2026. The local records supply this lesson’s numbers and refusals.
- Google ML Crash Course: monitoring: distinguish data checks, distributions and live model quality.
- Python hashlib: deterministic byte digests used by this local implementation.
- Python HTTP server: local server APIs and production limitations.
- Cloud Deploy canary concepts: subset rollout terminology. This lab does not run Cloud Deploy or reproduce its orchestration.