A candidate model can produce a valid answer while differing from the predictor callers currently use. Sending its result to callers immediately would change the application before you have inspected those differences. Shadow evaluation sends the same input to both selections but returns only the live result.
When you need this. Use shadow evaluation when you need to inspect a candidate on the same inputs before changing the response callers receive.
The live path owns the returned prediction. The shadow path supplies a separate observation in an audit entry. A disagreement identifies an input worth inspecting; it does not tell you which answer is correct. This lab uses the recorded Rice model and a clearly marked parameter fixture whose bias is increased by one. That fixture is not a newly trained model.
1. Follow the decision boundary
Router.infer() calculates the live answer first, then evaluates the candidate inside an expected-error boundary. It stores the candidate result or shadow_error separately and returns the original answer object. The exercise sends actual HTTP requests to a loopback server and compares every returned JSON response with a direct live-model prediction.
The lab reuses an exact copy of the recorded Rice predictor, bundle and dataset from registry and serving. It performs no training and uses no cloud service. Monitoring fixtures are explicitly authored; the rollout parameter variant is labeled in the result. Keep the complete extracted mlops-rollout-monitoring/ directory together; Python’s standard library is sufficient.
Read the implementation for this activity
"""Local routing around a recorded Rice predictor; no cloud deployment."""
import copy
import hashlib
import threading
from http.server import BaseHTTPRequestHandler, HTTPServer
from pathlib import Path
from predictor import decode, encode, digest, validate, predict, CONTRACT
HERE=Path(__file__).resolve().parent
SALT='rice-canary-fixture-v1'

def selected(data, expected, contract=CONTRACT):
    if digest(data)!=expected:raise ValueError('selected model digest mismatch')
    bundle=validate(decode(data))
    if bundle['contract']!=contract:raise ValueError('serving feature contract incompatible')
    return {'bundle':bundle,'version':expected}

def bundles():
    raw=(HERE/'baseline-model.json').read_bytes();live=selected(raw,digest(raw))
    altered=copy.deepcopy(live['bundle']);altered['bias']+=1.0
    # Deliberate parameter fixture, not an independently trained candidate.
    altered['fixture_variant']='recorded baseline bias plus 1.0; no training'
    raw=encode(altered)
    return live,selected(raw,digest(raw))

def identity(value):
    if not isinstance(value,str) or not 1<=len(value)<=80:raise ValueError('bounded nonempty identity required')
    return value

def cohort(user, basis_points=2000):
    identity(user)
    if type(basis_points) is not int or not 0<=basis_points<=10000:raise ValueError('invalid canary allocation')
    bucket=int.from_bytes(hashlib.sha256((SALT+':'+user).encode()).digest()[:8],'big')%10000
    return 'canary' if bucket<basis_points else 'control'

class Router:
    def __init__(self,live,candidate):
        self.live,self.candidate=live,candidate
        self.active=live
        self.audit=[]
        self.lock=threading.Lock()
    def infer(self,request,mode='shadow',basis_points=2000):
        if not isinstance(request,dict) or set(request)!={'id','user','input'}:raise ValueError('routing envelope mismatch')
        identity(request['id']);identity(request['user'])
        if mode not in ('shadow','canary','active'):raise ValueError('unknown route mode')
        arm=cohort(request['user'],basis_points) if mode=='canary' else 'control'
        with self.lock:chosen=self.active if mode=='active' else self.candidate if arm=='canary' else self.live
        answer=predict(chosen['bundle'],request['input'],chosen['version'])
        entry={'id':request['id'],'user':request['user'],'arm':arm,'served':answer}
        if mode=='shadow':
            try:entry['shadow']=predict(self.candidate['bundle'],request['input'],self.candidate['version'])
            except (ValueError,TypeError,OverflowError,KeyError) as error:entry['shadow_error']=type(error).__name__
        with self.lock:self.audit.append(entry)
        return answer
    def rollback(self,data,expected,contract=CONTRACT):
        candidate=selected(data,expected,contract)
        # Swap the complete local selection after every check has succeeded.
        with self.lock:
            previous=self.active['version'];self.active=candidate
        return {'previous':previous,'selected':expected,'contract':contract}

def server(router,mode='shadow',basis_points=2000):
    class Handler(BaseHTTPRequestHandler):
        def log_message(self,*_):pass
        def reply(self,status,value):
            data=encode(value);self.send_response(status);self.send_header('Content-Type','application/json')
            self.send_header('Content-Length',str(len(data)));self.end_headers();self.wfile.write(data)
        def do_POST(self):
            if self.path!='/predict':self.reply(404,{'error':'unknown route'});return
            try:
                size=int(self.headers.get('Content-Length','0'))
                if not 0<size<=4096:self.reply(413,{'error':'body size'});return
                if self.headers.get_content_type()!='application/json':self.reply(415,{'error':'content type'});return
                self.reply(200,router.infer(decode(self.rfile.read(size)),mode,basis_points))
            except (ValueError,TypeError,OverflowError,KeyError):self.reply(422,{'error':'invalid request'})
    return HTTPServer(('127.0.0.1',0),Handler)
Download the complete lab, extract it and open mlops-rollout-monitoring/. The candidate is an intentionally altered parameter fixture used to demonstrate routing. It has not been approved by the earlier quality gate for a real release.
2. Run the focused activity
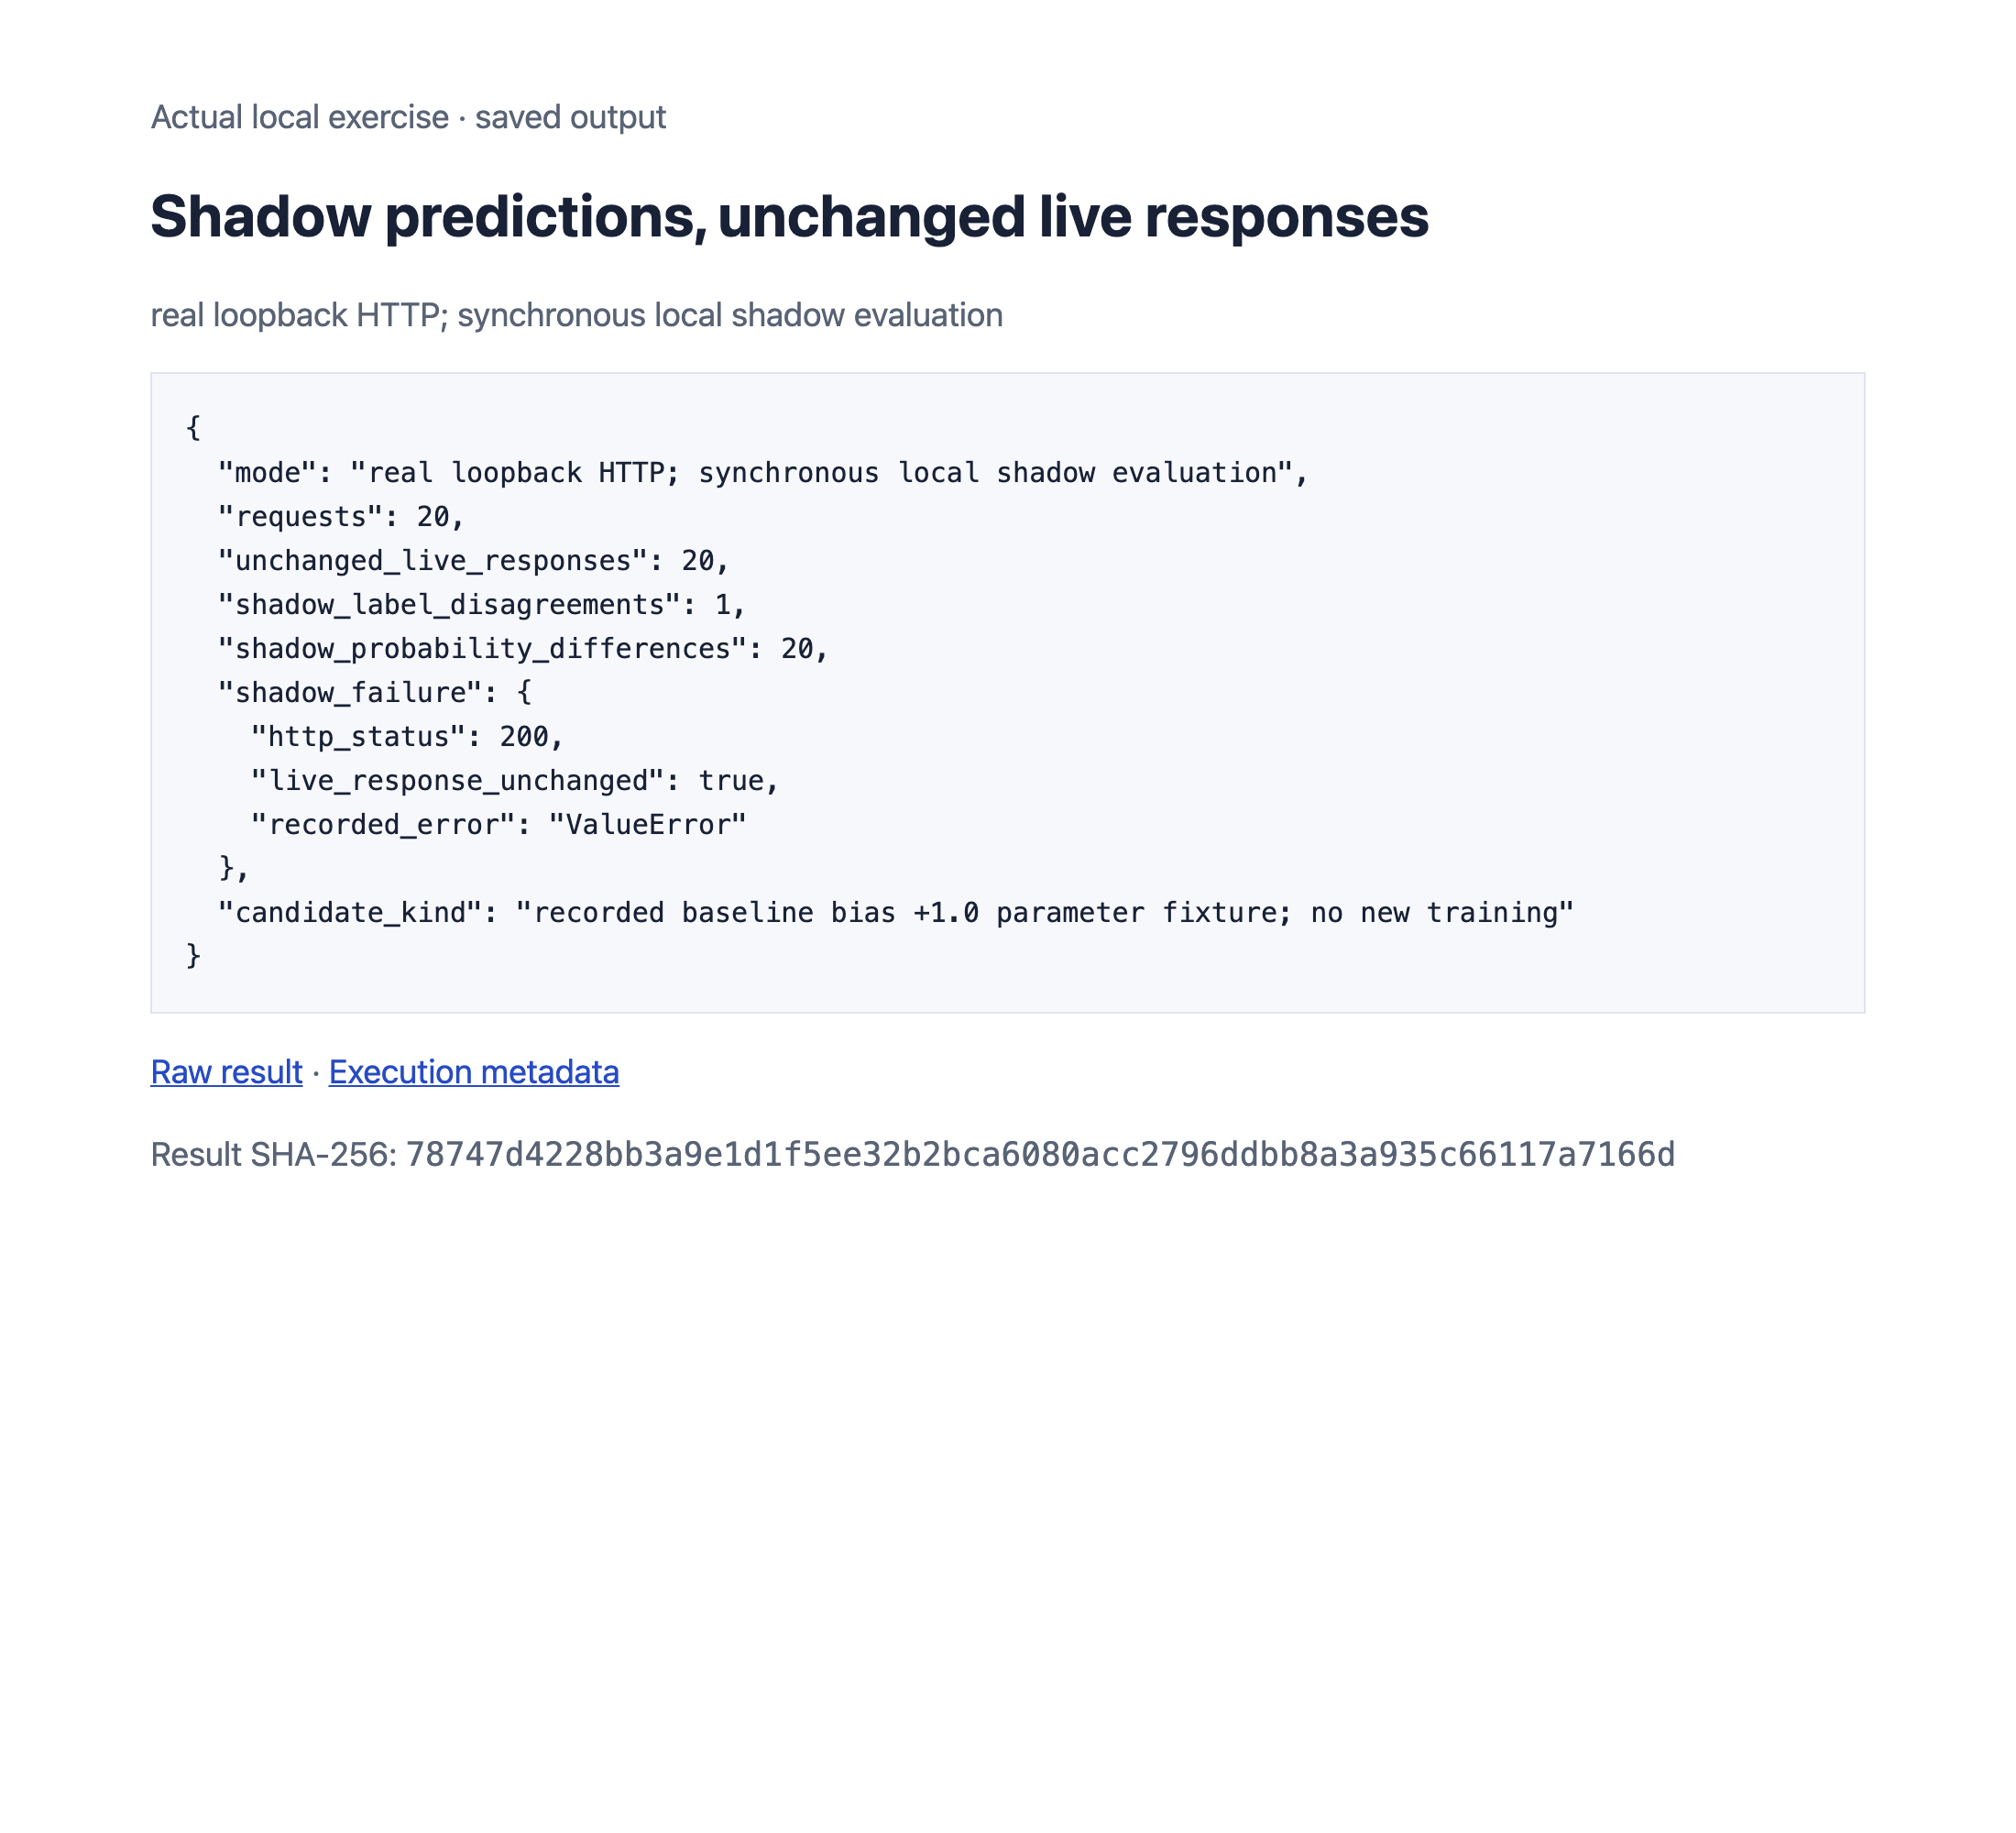
Run python exercise.py shadow. Follow one routing envelope: id names the request, user is a synthetic routing key, and input carries the existing named-feature contract. Inspect unchanged_live_responses, then the candidate label and probability difference counts. Only the live model digest appears in the response; the candidate digest identifies the separate audit computation.
python exercise.py shadow{
"mode": "real loopback HTTP; synchronous local shadow evaluation",
"requests": 20,
"unchanged_live_responses": 20,
"shadow_label_disagreements": 1,
"shadow_probability_differences": 20,
"shadow_failure": {
"http_status": 200,
"live_response_unchanged": true,
"recorded_error": "ValueError"
},
"live_version": "a4692350c5e6d1f231eea8c5eb3354c24276870e73a60922a10abb07abffa5f6",
"candidate_version": "22c31b9297103bf62c29b1560bf4b0236a29316bebba13b7e9531675fe76dfdb",
"candidate_kind": "recorded baseline bias +1.0 parameter fixture; no new training"
}The raw result, execution metadata and locally generated actual-output report retain the computed counts and source identities. Opening the report does not repeat execution. --record deliberately replaces that stage’s saved files; ordinary execution leaves them unchanged.

3. Inspect refusals before acting
| Failure condition | Required behavior |
|---|---|
| Candidate failure changes live response | A candidate error must leave the live response intact and record its failure separately. |
| Unknown request fields | Unknown envelope fields must be refused before prediction. |
The exercise then substitutes an incompatible candidate contract. The saved shadow_failure reports HTTP 200, an unchanged live response and a recorded ValueError. test_shadow_http_does_not_change_live_response checks those observations. An unknown envelope field is rejected before prediction by test_shadow_and_active_envelopes_refuse_unknown_fields.
python -m unittest -v test_continuation.pyIn a separate copy, change the fixture bias and predict which probability values will move before running again. Explain why observing more disagreements alone cannot select the better model.
How the result should guide the next step
Shadow evaluation here is synchronous. It adds computation before the response is sent; the error boundary does not stop a hanging candidate or preserve latency. The single-process HTTP server is a local teaching adapter with no authentication. Use the audit comparison to investigate, rather than promoting a fixture because its response shape looks correct.
Check your understanding
Read the explanation
Shadow evaluation is observational here. The candidate error is retained separately and does not replace the successful live prediction.
References
Official primary sources checked October 24, 2026. The local records supply this lesson’s numbers and refusals.
- Google ML Crash Course: monitoring: distinguish data checks, distributions and live model quality.
- Python hashlib: deterministic byte digests used by this local implementation.
- Python HTTP server: local server APIs and production limitations.
- Cloud Deploy canary concepts: subset rollout terminology. This lab does not run Cloud Deploy or reproduce its orchestration.