When you need this. A team must choose between a cheaper accelerator and one with more memory bandwidth for a code assistant. The answer depends on prompt length, active batch size, context length, and the latency budget. Build a roofline estimate to decide what to benchmark next.
What you run. Generic roofline calculator. Device specifications and prices are hypothetical inputs; no accelerator ranking was measured.
This lesson builds on budget model weights, kv cache, and runtime memory.
Find the limiting resource
Arithmetic intensity is useful operations divided by bytes moved. A roofline model bounds work by the slower of compute capacity and memory transfer capacity. Prefill can reuse weights across many input tokens; a small decode batch has less weight reuse. Larger batches and long cache reads change that balance.
The calculator uses generic example devices. Its compute, bandwidth, memory, and hourly prices are explicit scenario inputs. The reported latency is a lower-bound estimate, not a measured device recommendation. Attention, communication, host work, and scheduling can dominate outside this simplified model.
compute_prefill_metrics() and compute_decode_step_metrics() estimate different phases, then check whether the weight and cache payload fits. Inspect ModelWorkload before comparing example device outputs. The first lesson’s real prefill/decode runs show the distinction without pretending to test these devices.
Explore the roofline estimate
Download the lab from this page, extract it, and run these commands from its directory. The default command reads saved run records or runs the explicitly described local algorithm; it never downloads a model or calls a paid API.
python3 lab.py
python3 -m unittest -v test_lab.py
Read lab.py
"""GPU roofline model and hardware selector for prefill and decode workloads."""

from __future__ import annotations

from dataclasses import asdict, dataclass
import json


@dataclass(frozen=True)
class GpuSpec:
    name: str
    memory_gb: float
    bandwidth_gbps: float
    bf16_tflops: float
    hourly_cost_usd: float

    @property
    def ridge_point_flops_per_byte(self) -> float:
        """Minimum operational intensity (FLOPs/byte) required to reach peak TFLOPS."""
        return (self.bf16_tflops * 1e12) / (self.bandwidth_gbps * 1e9)


@dataclass(frozen=True)
class ModelWorkload:
    model_name: str
    active_params_b: float
    bytes_per_param: int
    kv_bytes_per_token: int
    prompt_tokens: int
    output_tokens: int
    batch_size: int
    activation_overhead_gb: float = 2.0

    def validate(self) -> None:
        if self.active_params_b <= 0 or self.bytes_per_param <= 0:
            raise ValueError(
                "Model parameter count and bytes per parameter must be positive"
            )
        if self.prompt_tokens <= 0 or self.output_tokens <= 0 or self.batch_size <= 0:
            raise ValueError(
                "Prompt tokens, output tokens, and batch size must be positive integers"
            )

    @property
    def weight_bytes(self) -> float:
        return self.active_params_b * 1e9 * self.bytes_per_param

    @property
    def total_kv_bytes(self) -> float:
        seq_len = self.prompt_tokens + self.output_tokens
        return float(self.batch_size * seq_len * self.kv_bytes_per_token)

    @property
    def required_memory_gb(self) -> float:
        return (
            self.weight_bytes + self.total_kv_bytes
        ) / 1e9 + self.activation_overhead_gb


@dataclass(frozen=True)
class WorkloadPhaseMetrics:
    phase: str
    flops: float
    hbm_bytes: float
    operational_intensity: float
    ridge_point: float
    regime: str
    roofline_tflops_bound: float
    latency_ms: float


GPU_SPECS: dict[str, GpuSpec] = {
    "example-small": GpuSpec(
        name="example-small",
        memory_gb=48.0,
        bandwidth_gbps=864.0,
        bf16_tflops=362.0,
        hourly_cost_usd=1.55,
    ),
    "example-fast": GpuSpec(
        name="example-fast",
        memory_gb=80.0,
        bandwidth_gbps=3350.0,
        bf16_tflops=989.0,
        hourly_cost_usd=3.20,
    ),
    "example-large-memory": GpuSpec(
        name="example-large-memory",
        memory_gb=141.0,
        bandwidth_gbps=4800.0,
        bf16_tflops=989.0,
        hourly_cost_usd=3.80,
    ),
    "example-wide-bandwidth": GpuSpec(
        name="example-wide-bandwidth",
        memory_gb=192.0,
        bandwidth_gbps=8000.0,
        bf16_tflops=2250.0,
        hourly_cost_usd=6.20,
    ),
}


def compute_prefill_metrics(
    gpu: GpuSpec, workload: ModelWorkload
) -> WorkloadPhaseMetrics:
    workload.validate()
    total_prefill_tokens = workload.batch_size * workload.prompt_tokens
    flops = 2.0 * (workload.active_params_b * 1e9) * total_prefill_tokens
    kv_write_bytes = float(total_prefill_tokens * workload.kv_bytes_per_token)
    hbm_bytes = workload.weight_bytes + kv_write_bytes
    intensity = flops / hbm_bytes
    ridge = gpu.ridge_point_flops_per_byte
    regime = "compute-bound" if intensity >= ridge else "bandwidth-bound"
    compute_seconds = flops / (gpu.bf16_tflops * 1e12)
    memory_seconds = hbm_bytes / (gpu.bandwidth_gbps * 1e9)
    latency_s = max(compute_seconds, memory_seconds)
    roofline_tflops_bound = (flops / latency_s) / 1e12
    return WorkloadPhaseMetrics(
        phase="prefill",
        flops=round(flops, 2),
        hbm_bytes=round(hbm_bytes, 2),
        operational_intensity=round(intensity, 2),
        ridge_point=round(ridge, 2),
        regime=regime,
        roofline_tflops_bound=round(roofline_tflops_bound, 2),
        latency_ms=round(latency_s * 1000.0, 3),
    )


def compute_decode_step_metrics(
    gpu: GpuSpec, workload: ModelWorkload
) -> WorkloadPhaseMetrics:
    workload.validate()
    flops = 2.0 * (workload.active_params_b * 1e9) * workload.batch_size
    avg_context_len = workload.prompt_tokens + (workload.output_tokens / 2.0)
    kv_read_bytes = float(
        workload.batch_size * avg_context_len * workload.kv_bytes_per_token
    )
    hbm_bytes = workload.weight_bytes + kv_read_bytes
    intensity = flops / hbm_bytes
    ridge = gpu.ridge_point_flops_per_byte
    regime = "compute-bound" if intensity >= ridge else "bandwidth-bound"
    compute_seconds = flops / (gpu.bf16_tflops * 1e12)
    memory_seconds = hbm_bytes / (gpu.bandwidth_gbps * 1e9)
    latency_s = max(compute_seconds, memory_seconds)
    roofline_tflops_bound = (flops / latency_s) / 1e12
    return WorkloadPhaseMetrics(
        phase="decode_step",
        flops=round(flops, 2),
        hbm_bytes=round(hbm_bytes, 2),
        operational_intensity=round(intensity, 2),
        ridge_point=round(ridge, 2),
        regime=regime,
        roofline_tflops_bound=round(roofline_tflops_bound, 2),
        latency_ms=round(latency_s * 1000.0, 3),
    )


def evaluate_gpu_for_workload(
    gpu: GpuSpec,
    workload: ModelWorkload,
    require_single_card_fit: bool = True,
) -> dict[str, object]:
    workload.validate()
    required_gb = workload.required_memory_gb
    fits = required_gb <= gpu.memory_gb
    if require_single_card_fit and not fits:
        raise ValueError(
            f"{gpu.name} has {gpu.memory_gb:.1f} GB VRAM, below required {required_gb:.2f} GB"
        )
    prefill = compute_prefill_metrics(gpu, workload)
    decode = compute_decode_step_metrics(gpu, workload)
    ttft_ms = prefill.latency_ms
    tpot_ms = decode.latency_ms
    total_latency_s = (ttft_ms + tpot_ms * (workload.output_tokens - 1)) / 1000.0
    decode_tokens_per_sec = workload.batch_size / (tpot_ms / 1000.0)
    end_to_end_tokens_per_sec = (
        workload.batch_size * workload.output_tokens
    ) / total_latency_s
    tokens_per_dollar = end_to_end_tokens_per_sec * 3600 / gpu.hourly_cost_usd
    return {
        "gpu": gpu.name,
        "memory_gb": gpu.memory_gb,
        "required_memory_gb": round(required_gb, 2),
        "fits_single_gpu": fits,
        "ridge_point_flops_per_byte": round(gpu.ridge_point_flops_per_byte, 2),
        "prefill": asdict(prefill),
        "decode": asdict(decode),
        "ttft_ms": round(ttft_ms, 2),
        "tpot_ms": round(tpot_ms, 3),
        "decode_tokens_per_sec": round(decode_tokens_per_sec, 2),
        "end_to_end_tokens_per_sec": round(end_to_end_tokens_per_sec, 2),
        "tokens_per_dollar": round(tokens_per_dollar, 2),
    }


def build_report() -> dict[str, object]:
    # 8B BF16 model (16 GB weights, 128 KB/token KV cache for 32 layers GQA)
    small_model_comparisons = []
    for name, gpu in GPU_SPECS.items():
        workload = ModelWorkload(
            model_name="Llama-3-8B-BF16",
            active_params_b=8.0,
            bytes_per_param=2,
            kv_bytes_per_token=131072,
            prompt_tokens=2048,
            output_tokens=256,
            batch_size=8,
        )
        small_model_comparisons.append(evaluate_gpu_for_workload(gpu, workload))

    # 70B BF16 model (140 GB weights? Or 32B BF16 = 64 GB weights + KV cache)
    # Let's evaluate a 32B BF16 model (64 GB weights) with long context that fits H200/example-wide-bandwidth
    # and overflows example-small/H100 when KV cache grows.
    large_workload = ModelWorkload(
        model_name="Qwen-32B-BF16-LongContext",
        active_params_b=32.0,
        bytes_per_param=2,
        kv_bytes_per_token=262144,
        prompt_tokens=4096,
        output_tokens=512,
        batch_size=16,
    )
    large_model_comparisons = [
        evaluate_gpu_for_workload(gpu, large_workload, require_single_card_fit=False)
        for gpu in GPU_SPECS.values()
    ]

    batch_sweep = []
    for batch_size in (1, 8, 32, 128, 256):
        w = ModelWorkload(
            model_name="Llama-3-8B-BF16",
            active_params_b=8.0,
            bytes_per_param=2,
            kv_bytes_per_token=131072,
            prompt_tokens=1024,
            output_tokens=128,
            batch_size=batch_size,
        )
        metrics = evaluate_gpu_for_workload(GPU_SPECS["example-fast"], w)
        batch_sweep.append(
            {
                "batch_size": batch_size,
                "prefill_intensity": metrics["prefill"]["operational_intensity"],
                "prefill_regime": metrics["prefill"]["regime"],
                "decode_intensity": metrics["decode"]["operational_intensity"],
                "decode_regime": metrics["decode"]["regime"],
                "decode_roofline_tflops_bound": metrics["decode"][
                    "roofline_tflops_bound"
                ],
                "tpot_ms": metrics["tpot_ms"],
                "decode_tokens_per_sec": metrics["decode_tokens_per_sec"],
            }
        )

    return {
        "gpu_catalog": [
            {
                **asdict(gpu),
                "ridge_point_flops_per_byte": round(gpu.ridge_point_flops_per_byte, 2),
            }
            for gpu in GPU_SPECS.values()
        ],
        "llama_8b_batch8": small_model_comparisons,
        "qwen_32b_long_context": large_model_comparisons,
        "h100_batch_sweep": batch_sweep,
    }


def main() -> None:
    print(
        json.dumps(
            {
                "execution_mode": "CPU algorithm with controlled inputs; any latency/capacity coefficients are assumptions",
                **build_report(),
            },
            indent=2,
        )
    )


if __name__ == "__main__":
    main()
The example catalog is input data for a sensitivity calculation. Its prices and performance figures do not describe current products. Use the real local prefill/decode record to learn measurement boundaries, then benchmark hardware candidates on their own runtime.
| Quantity | Recorded value |
|---|---|
| Example device count | 4 |
Inspect the complete local result
{
  "execution_mode": "CPU algorithm with controlled inputs; any latency/capacity coefficients are assumptions",
  "gpu_catalog": [
    {
      "name": "example-small",
      "memory_gb": 48.0,
      "bandwidth_gbps": 864.0,
      "bf16_tflops": 362.0,
      "hourly_cost_usd": 1.55,
      "ridge_point_flops_per_byte": 418.98
    },
    {
      "name": "example-fast",
      "memory_gb": 80.0,
      "bandwidth_gbps": 3350.0,
      "bf16_tflops": 989.0,
      "hourly_cost_usd": 3.2,
      "ridge_point_flops_per_byte": 295.22
    },
    {
      "name": "example-large-memory",
      "memory_gb": 141.0,
      "bandwidth_gbps": 4800.0,
      "bf16_tflops": 989.0,
      "hourly_cost_usd": 3.8,
      "ridge_point_flops_per_byte": 206.04
    },
    {
      "name": "example-wide-bandwidth",
      "memory_gb": 192.0,
      "bandwidth_gbps": 8000.0,
      "bf16_tflops": 2250.0,
      "hourly_cost_usd": 6.2,
      "ridge_point_flops_per_byte": 281.25
    }
  ],
  "llama_8b_batch8": [
    {
      "gpu": "example-small",
      "memory_gb": 48.0,
      "required_memory_gb": 20.42,
      "fits_single_gpu": true,
      "ridge_point_flops_per_byte": 418.98,
      "prefill": {
        "phase": "prefill",
        "flops": 262144000000000.0,
        "hbm_bytes": 18147483648.0,
        "operational_intensity": 14445.2,
        "ridge_point": 418.98,
        "regime": "compute-bound",
        "roofline_tflops_bound": 362.0,
        "latency_ms": 724.155
      },
      "decode": {
        "phase": "decode_step",
        "flops": 128000000000.0,
        "hbm_bytes": 18281701376.0,
        "operational_intensity": 7.0,
        "ridge_point": 418.98,
        "regime": "bandwidth-bound",
        "roofline_tflops_bound": 6.05,
        "latency_ms": 21.159
      },
      "ttft_ms": 724.15,
      "tpot_ms": 21.159,
      "decode_tokens_per_sec": 378.09,
      "end_to_end_tokens_per_sec": 334.66,
      "tokens_per_dollar": 777267.7
    },
    {
      "gpu": "example-fast",
      "memory_gb": 80.0,
      "required_memory_gb": 20.42,
      "fits_single_gpu": true,
      "ridge_point_flops_per_byte": 295.22,
      "prefill": {
        "phase": "prefill",
        "flops": 262144000000000.0,
        "hbm_bytes": 18147483648.0,
        "operational_intensity": 14445.2,
        "ridge_point": 295.22,
        "regime": "compute-bound",
        "roofline_tflops_bound": 989.0,
        "latency_ms": 265.06
      },
      "decode": {
        "phase": "decode_step",
        "flops": 128000000000.0,
        "hbm_bytes": 18281701376.0,
        "operational_intensity": 7.0,
        "ridge_point": 295.22,
        "regime": "bandwidth-bound",
        "roofline_tflops_bound": 23.46,
        "latency_ms": 5.457
      },
      "ttft_ms": 265.06,
      "tpot_ms": 5.457,
      "decode_tokens_per_sec": 1466.01,
      "end_to_end_tokens_per_sec": 1236.27,
      "tokens_per_dollar": 1390804.63
    },
    {
      "gpu": "example-large-memory",
      "memory_gb": 141.0,
      "required_memory_gb": 20.42,
      "fits_single_gpu": true,
      "ridge_point_flops_per_byte": 206.04,
      "prefill": {
        "phase": "prefill",
        "flops": 262144000000000.0,
        "hbm_bytes": 18147483648.0,
        "operational_intensity": 14445.2,
        "ridge_point": 206.04,
        "regime": "compute-bound",
        "roofline_tflops_bound": 989.0,
        "latency_ms": 265.06
      },
      "decode": {
        "phase": "decode_step",
        "flops": 128000000000.0,
        "hbm_bytes": 18281701376.0,
        "operational_intensity": 7.0,
        "ridge_point": 206.04,
        "regime": "bandwidth-bound",
        "roofline_tflops_bound": 33.61,
        "latency_ms": 3.809
      },
      "ttft_ms": 265.06,
      "tpot_ms": 3.809,
      "decode_tokens_per_sec": 2100.29,
      "end_to_end_tokens_per_sec": 1656.48,
      "tokens_per_dollar": 1569298.89
    },
    {
      "gpu": "example-wide-bandwidth",
      "memory_gb": 192.0,
      "required_memory_gb": 20.42,
      "fits_single_gpu": true,
      "ridge_point_flops_per_byte": 281.25,
      "prefill": {
        "phase": "prefill",
        "flops": 262144000000000.0,
        "hbm_bytes": 18147483648.0,
        "operational_intensity": 14445.2,
        "ridge_point": 281.25,
        "regime": "compute-bound",
        "roofline_tflops_bound": 2250.0,
        "latency_ms": 116.508
      },
      "decode": {
        "phase": "decode_step",
        "flops": 128000000000.0,
        "hbm_bytes": 18281701376.0,
        "operational_intensity": 7.0,
        "ridge_point": 281.25,
        "regime": "bandwidth-bound",
        "roofline_tflops_bound": 56.01,
        "latency_ms": 2.285
      },
      "ttft_ms": 116.51,
      "tpot_ms": 2.285,
      "decode_tokens_per_sec": 3501.09,
      "end_to_end_tokens_per_sec": 2929.13,
      "tokens_per_dollar": 1700786.9
    }
  ],
  "qwen_32b_long_context": [
    {
      "gpu": "example-small",
      "memory_gb": 48.0,
      "required_memory_gb": 85.33,
      "fits_single_gpu": false,
      "ridge_point_flops_per_byte": 418.98,
      "prefill": {
        "phase": "prefill",
        "flops": 4194304000000000.0,
        "hbm_bytes": 81179869184.0,
        "operational_intensity": 51666.8,
        "ridge_point": 418.98,
        "regime": "compute-bound",
        "roofline_tflops_bound": 362.0,
        "latency_ms": 11586.475
      },
      "decode": {
        "phase": "decode_step",
        "flops": 1024000000000.0,
        "hbm_bytes": 82253611008.0,
        "operational_intensity": 12.45,
        "ridge_point": 418.98,
        "regime": "bandwidth-bound",
        "roofline_tflops_bound": 10.76,
        "latency_ms": 95.201
      },
      "ttft_ms": 11586.48,
      "tpot_ms": 95.201,
      "decode_tokens_per_sec": 168.07,
      "end_to_end_tokens_per_sec": 136.0,
      "tokens_per_dollar": 315876.78
    },
    {
      "gpu": "example-fast",
      "memory_gb": 80.0,
      "required_memory_gb": 85.33,
      "fits_single_gpu": false,
      "ridge_point_flops_per_byte": 295.22,
      "prefill": {
        "phase": "prefill",
        "flops": 4194304000000000.0,
        "hbm_bytes": 81179869184.0,
        "operational_intensity": 51666.8,
        "ridge_point": 295.22,
        "regime": "compute-bound",
        "roofline_tflops_bound": 989.0,
        "latency_ms": 4240.954
      },
      "decode": {
        "phase": "decode_step",
        "flops": 1024000000000.0,
        "hbm_bytes": 82253611008.0,
        "operational_intensity": 12.45,
        "ridge_point": 295.22,
        "regime": "bandwidth-bound",
        "roofline_tflops_bound": 41.71,
        "latency_ms": 24.553
      },
      "ttft_ms": 4240.95,
      "tpot_ms": 24.553,
      "decode_tokens_per_sec": 651.65,
      "end_to_end_tokens_per_sec": 487.98,
      "tokens_per_dollar": 548978.69
    },
    {
      "gpu": "example-large-memory",
      "memory_gb": 141.0,
      "required_memory_gb": 85.33,
      "fits_single_gpu": true,
      "ridge_point_flops_per_byte": 206.04,
      "prefill": {
        "phase": "prefill",
        "flops": 4194304000000000.0,
        "hbm_bytes": 81179869184.0,
        "operational_intensity": 51666.8,
        "ridge_point": 206.04,
        "regime": "compute-bound",
        "roofline_tflops_bound": 989.0,
        "latency_ms": 4240.954
      },
      "decode": {
        "phase": "decode_step",
        "flops": 1024000000000.0,
        "hbm_bytes": 82253611008.0,
        "operational_intensity": 12.45,
        "ridge_point": 206.04,
        "regime": "bandwidth-bound",
        "roofline_tflops_bound": 59.76,
        "latency_ms": 17.136
      },
      "ttft_ms": 4240.95,
      "tpot_ms": 17.136,
      "decode_tokens_per_sec": 933.71,
      "end_to_end_tokens_per_sec": 630.28,
      "tokens_per_dollar": 597104.98
    },
    {
      "gpu": "example-wide-bandwidth",
      "memory_gb": 192.0,
      "required_memory_gb": 85.33,
      "fits_single_gpu": true,
      "ridge_point_flops_per_byte": 281.25,
      "prefill": {
        "phase": "prefill",
        "flops": 4194304000000000.0,
        "hbm_bytes": 81179869184.0,
        "operational_intensity": 51666.8,
        "ridge_point": 281.25,
        "regime": "compute-bound",
        "roofline_tflops_bound": 2250.0,
        "latency_ms": 1864.135
      },
      "decode": {
        "phase": "decode_step",
        "flops": 1024000000000.0,
        "hbm_bytes": 82253611008.0,
        "operational_intensity": 12.45,
        "ridge_point": 281.25,
        "regime": "bandwidth-bound",
        "roofline_tflops_bound": 99.59,
        "latency_ms": 10.282
      },
      "ttft_ms": 1864.13,
      "tpot_ms": 10.282,
      "decode_tokens_per_sec": 1556.12,
      "end_to_end_tokens_per_sec": 1150.85,
      "tokens_per_dollar": 668233.6
    }
  ],
  "h100_batch_sweep": [
    {
      "batch_size": 1,
      "prefill_intensity": 1015.48,
      "prefill_regime": "compute-bound",
      "decode_intensity": 0.99,
      "decode_regime": "bandwidth-bound",
      "decode_roofline_tflops_bound": 3.32,
      "tpot_ms": 4.819,
      "decode_tokens_per_sec": 207.51
    },
    {
      "batch_size": 8,
      "prefill_intensity": 7676.82,
      "prefill_regime": "compute-bound",
      "decode_intensity": 7.47,
      "decode_regime": "bandwidth-bound",
      "decode_roofline_tflops_bound": 25.02,
      "tpot_ms": 5.117,
      "decode_tokens_per_sec": 1563.42
    },
    {
      "batch_size": 32,
      "prefill_intensity": 25833.4,
      "prefill_regime": "compute-bound",
      "decode_intensity": 24.9,
      "decode_regime": "bandwidth-bound",
      "decode_roofline_tflops_bound": 83.41,
      "tpot_ms": 6.138,
      "decode_tokens_per_sec": 5213.42
    },
    {
      "batch_size": 128,
      "prefill_intensity": 63205.55,
      "prefill_regime": "compute-bound",
      "decode_intensity": 59.79,
      "decode_regime": "bandwidth-bound",
      "decode_roofline_tflops_bound": 200.29,
      "tpot_ms": 10.225,
      "decode_tokens_per_sec": 12518.34
    },
    {
      "batch_size": 256,
      "prefill_intensity": 83286.85,
      "prefill_regime": "compute-bound",
      "decode_intensity": 78.01,
      "decode_regime": "bandwidth-bound",
      "decode_roofline_tflops_bound": 261.33,
      "tpot_ms": 15.674,
      "decode_tokens_per_sec": 16332.78
    }
  ]
}
This image is an application-generated report of the saved program result, not a new inference run. Open the full-resolution report or read the raw result.
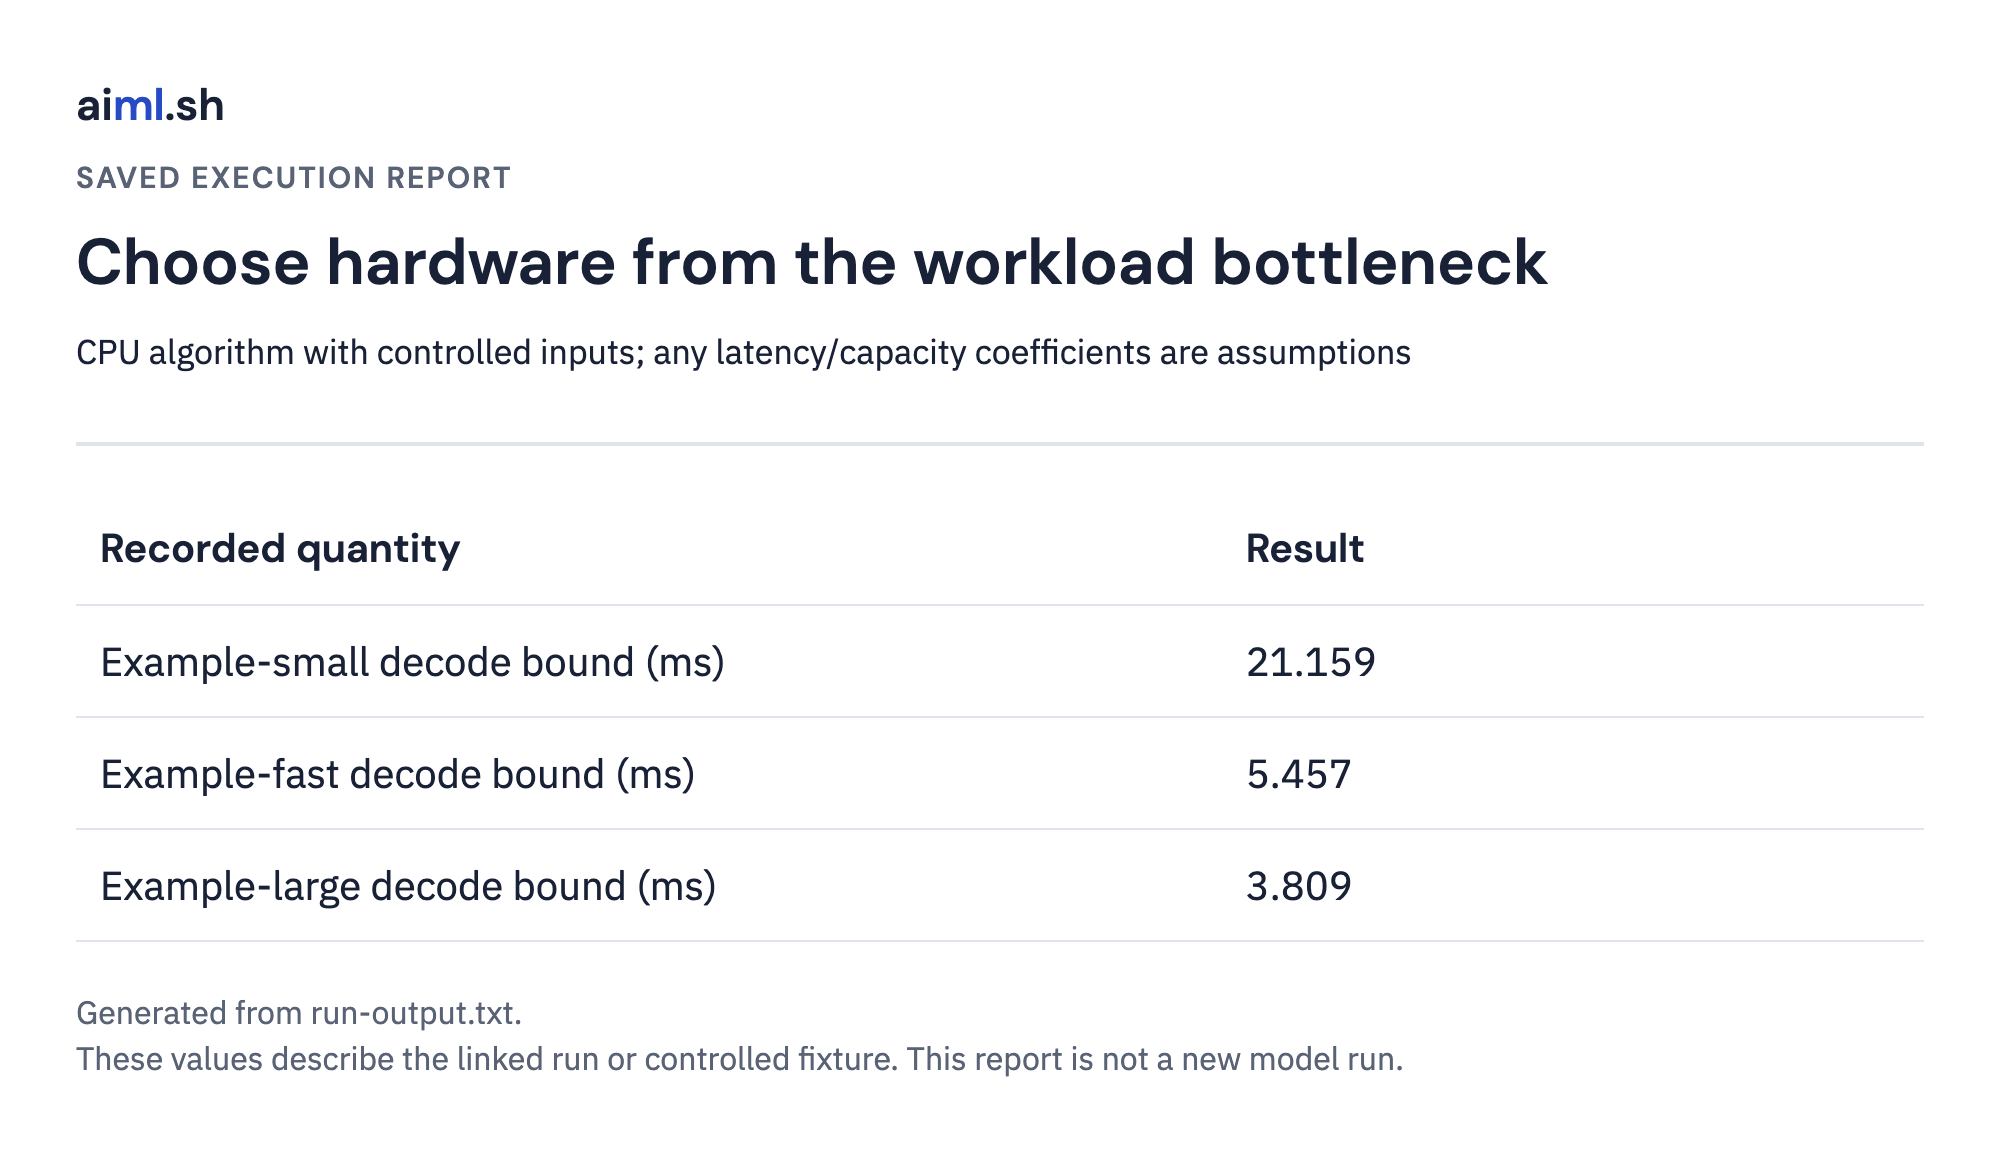
Compare capacity and latency costs
A faster arithmetic unit may do little for bandwidth-bound decode. More memory can increase concurrency without reducing single-request latency. Splitting weights across devices adds communication, so an aggregate bandwidth figure is not automatically usable by one request.
Compute capacity is not the limiter. Increasing arithmetic peak does not resolve a bandwidth-bound small decode batch in this cost model.
Weight and cache fit. If the payload exceeds the example device memory, the single-device configuration is rejected before its performance estimate is compared.
Read the executable checks
"""Unit and failure-boundary tests for the GPU roofline and selector lab."""

from __future__ import annotations

import unittest

from lab import (
    GPU_SPECS,
    GpuSpec,
    ModelWorkload,
    build_report,
    compute_decode_step_metrics,
    compute_prefill_metrics,
    evaluate_gpu_for_workload,
)


class GpuRooflineTest(unittest.TestCase):
    def test_ridge_points_reflect_compute_to_bandwidth_ratio(self) -> None:
        self.assertAlmostEqual(
            GPU_SPECS["example-small"].ridge_point_flops_per_byte, 418.98, places=2
        )
        self.assertAlmostEqual(
            GPU_SPECS["example-fast"].ridge_point_flops_per_byte, 295.22, places=2
        )
        self.assertAlmostEqual(
            GPU_SPECS["example-large-memory"].ridge_point_flops_per_byte,
            206.04,
            places=2,
        )
        self.assertAlmostEqual(
            GPU_SPECS["example-wide-bandwidth"].ridge_point_flops_per_byte,
            281.25,
            places=2,
        )

    def test_prefill_is_compute_bound_while_small_batch_decode_is_bandwidth_bound(
        self,
    ) -> None:
        workload = ModelWorkload(
            model_name="Llama-3-8B-BF16",
            active_params_b=8.0,
            bytes_per_param=2,
            kv_bytes_per_token=131072,
            prompt_tokens=2048,
            output_tokens=256,
            batch_size=8,
        )
        h100 = GPU_SPECS["example-fast"]
        prefill = compute_prefill_metrics(h100, workload)
        decode = compute_decode_step_metrics(h100, workload)
        self.assertEqual(prefill.regime, "compute-bound")
        self.assertGreater(
            prefill.operational_intensity, h100.ridge_point_flops_per_byte
        )
        self.assertEqual(decode.regime, "bandwidth-bound")
        self.assertLess(decode.operational_intensity, 20.0)

    def test_buying_peak_tflops_for_small_batch_decode_wastes_budget(self) -> None:
        """Doubling peak TFLOPS without raising HBM bandwidth leaves small-batch decode TPOT unchanged."""
        workload = ModelWorkload(
            model_name="Llama-3-8B-BF16",
            active_params_b=8.0,
            bytes_per_param=2,
            kv_bytes_per_token=131072,
            prompt_tokens=2048,
            output_tokens=256,
            batch_size=4,
        )
        h100 = GPU_SPECS["example-fast"]
        # Hypothetical chip with 2x BF16 TFLOPS but identical 3,350 GB/s HBM bandwidth
        double_compute_same_bw = GpuSpec(
            name="Hypothetical-2x-TFLOPS",
            memory_gb=80.0,
            bandwidth_gbps=h100.bandwidth_gbps,
            bf16_tflops=h100.bf16_tflops * 2.0,
            hourly_cost_usd=h100.hourly_cost_usd * 1.5,
        )
        h100_eval = evaluate_gpu_for_workload(h100, workload)
        hyp_eval = evaluate_gpu_for_workload(double_compute_same_bw, workload)
        self.assertEqual(h100_eval["tpot_ms"], hyp_eval["tpot_ms"])
        self.assertGreater(
            GPU_SPECS["example-large-memory"].bandwidth_gbps,
            h100.bandwidth_gbps,
        )
        h200_eval = evaluate_gpu_for_workload(
            GPU_SPECS["example-large-memory"], workload
        )
        self.assertLess(h200_eval["tpot_ms"], h100_eval["tpot_ms"])

    def test_insufficient_vram_rejects_single_card_fit(self) -> None:
        """A workload whose weights + KV cache + activations exceed GPU VRAM raises ValueError."""
        large_workload = ModelWorkload(
            model_name="Qwen-32B-BF16-LongContext",
            active_params_b=32.0,
            bytes_per_param=2,
            kv_bytes_per_token=262144,
            prompt_tokens=4096,
            output_tokens=512,
            batch_size=16,
        )
        with self.assertRaisesRegex(ValueError, "below required"):
            evaluate_gpu_for_workload(
                GPU_SPECS["example-small"], large_workload, require_single_card_fit=True
            )
        with self.assertRaisesRegex(ValueError, "below required"):
            evaluate_gpu_for_workload(
                GPU_SPECS["example-fast"], large_workload, require_single_card_fit=True
            )
        h200_fit = evaluate_gpu_for_workload(
            GPU_SPECS["example-large-memory"],
            large_workload,
            require_single_card_fit=True,
        )
        self.assertTrue(h200_fit["fits_single_gpu"])

    def test_report_structure_is_deterministic(self) -> None:
        report = build_report()
        self.assertEqual(len(report["gpu_catalog"]), 4)
        self.assertEqual(len(report["llama_8b_batch8"]), 4)
        self.assertEqual(len(report["h100_batch_sweep"]), 5)


class RooflineUnitsTests(unittest.TestCase):
    def test_first_output_token_has_no_decode_interval(self):
        from lab import GpuSpec, ModelWorkload, evaluate_gpu_for_workload

        gpu = GpuSpec("test", 100, 100, 10, 2)
        work = ModelWorkload("test", 0.01, 2, 16, 8, 1, 1)
        result = evaluate_gpu_for_workload(gpu, work)
        expected = 1000 / result["prefill"]["latency_ms"]
        self.assertAlmostEqual(result["end_to_end_tokens_per_sec"], expected, delta=0.2)
        self.assertAlmostEqual(
            result["tokens_per_dollar"],
            result["end_to_end_tokens_per_sec"] * 1800,
            delta=10,
        )


if __name__ == "__main__":
    unittest.main()


class GuardBoundaryTests(unittest.TestCase):
    def test_rejects_invalid_boundary_inputs_with_specific_reason(self):
        import lab
        cases = [('ModelWorkload("test",0,2,2,1,1,1).validate()', 'Model parameter'), ('ModelWorkload("test",1,2,2,0,1,1).validate()', 'Prompt tokens')]
        for code, reason in cases:
            with self.subTest(code=code):
                with self.assertRaisesRegex((ValueError, MemoryError, KeyError, RuntimeError), reason):
                    exec(code, vars(lab).copy())
Try a change and explain the result
Increase the active batch and inspect how arithmetic intensity changes. Then increase context length and observe cache traffic. Identify the next real benchmark you would run before spending money on hardware.
Read the explanation
A roofline estimate identifies a candidate limiter; the actual workload must confirm it.
Choose the next hardware benchmark
Get current specifications for the exact device and precision from its vendor. Measure sustained bandwidth, model compatibility, and full serving latency. Use an actual provider quote for cost; example prices here are not market prices.
References
Sources checked October 24, 2026. Runtime-specific commands and results apply to the recorded versions; linked rolling documentation can change. The application scenarios are teaching examples, not claims about an author’s production incident.