When you need this. A code assistant accepts a request immediately, then appears idle before text arrives. Adding replicas will not help if the delay is inside tokenization or prompt processing. Build a trace that separates the wait for the first token from the pace of later tokens.
What you run. Fresh local inference with a pinned Apache-2.0 model. The default command analyzes its committed record offline; the separate live runner executes the model.
Read the request timeline
Tokenization converts text into the model’s input IDs. Prefill evaluates that prompt and creates the attention key/value cache (KV cache). The final prompt position supplies logits for the first output token. Decode then feeds back one selected token at a time, reusing cached keys and values instead of recomputing the entire prefix.
Time to first token (TTFT) ends when the first output token is available at the measurement boundary. Time per output token (TPOT) averages intervals after that first token. A client-side trace also includes transport and queueing; this local trace starts before tokenization and has neither. A one-token response has no decode interval, so its TPOT is undefined.
LocalDecoder.run() performs real forward passes, records each selected token, and synchronizes the device before recording timestamps. It explicitly sets greedy decoding, an output cap, the attention backend, and whether to retain the cache. summarize() rejects inconsistent timing records before calculating medians.
Follow the saved prompt “Explain why a code assistant should stop generating when its user cancels.” Tokenization supplies its input IDs, prefill produces the first next-token scores, and each later decode step extends the same response. The cached and uncached runs use this same prompt so their token intervals can be compared.
Run and read the trace
Download the lab from this page, extract it, and run these commands from its directory. The default command analyzes the saved record in live-run.json. It does not download a model or call a paid API.
python3 lab.py
python3 -m unittest -v test_lab.py
Read lab.py
"""Summarize the committed real local-inference record without rerunning a model."""

import json
import math
import statistics
from pathlib import Path


def summarize(samples):
    if not samples:
        raise ValueError("At least one completed generation is required")
    for sample in samples:
        values = [sample["ttft_ms"], sample["e2e_ms"], *sample["itl_ms"]]
        if not all(math.isfinite(v) and v >= 0 for v in values):
            raise ValueError("Timing values must be finite and nonnegative")
        if sample["generated_tokens"] != len(sample["generated_token_ids"]):
            raise ValueError("Token count mismatch")
        if sample["ttft_ms"] < 0 or sample["e2e_ms"] < sample["ttft_ms"]:
            raise ValueError("Invalid token timing")
        if len(sample["itl_ms"]) != max(0, sample["generated_tokens"] - 1):
            raise ValueError("Missing token intervals")
        if not math.isclose(
            math.fsum(sample["itl_ms"]),
            sample["e2e_ms"] - sample["ttft_ms"],
            abs_tol=0.002 * max(1, len(sample["itl_ms"])),
        ):
            raise ValueError("Intervals do not account for end-to-end timing")

    return {
        "samples": len(samples),
        "median_ttft_ms": round(statistics.median(x["ttft_ms"] for x in samples), 3),
        "median_tpot_ms": (
            round(
                statistics.median(
                    statistics.fmean(x["itl_ms"]) for x in samples if x["itl_ms"]
                ),
                3,
            )
            if any(x["itl_ms"] for x in samples)
            else None
        ),
    }


def main():
    record = json.loads(Path("live-run.json").read_text())
    print(
        json.dumps(
            {
                "execution_mode": "offline analysis of fresh local inference record",
                "model": record["model"],
                "generation": record["generation"],
                "comparisons": {
                    run["name"]: summarize(run["samples"]) for run in record["runs"]
                },
                "batch_sweep": record["batch_sweep"],
                "prefix_reuse": record["prefix_reuse"],
            },
            indent=2,
        )
    )


if __name__ == "__main__":
    main()
Read live_inference.py
"""Real local text generation and measured inference experiments. Never downloads implicitly."""

from __future__ import annotations
import argparse
import hashlib
import json
import math
import platform
import statistics
import time
from pathlib import Path

MODEL_ID = "Qwen/Qwen2.5-0.5B-Instruct"
MODEL_REVISION = "7ae557604adf67be50417f59c2c2f167def9a775"


def percentile(values, q):
    return sorted(values)[max(0, math.ceil(len(values) * q) - 1)] if values else None


class LocalDecoder:
    def __init__(self, model_path, device):
        import torch
        from transformers import AutoModelForCausalLM, AutoTokenizer

        self.torch = torch
        self.device = device
        self.tokenizer = AutoTokenizer.from_pretrained(
            model_path, local_files_only=True
        )
        self.tokenizer.padding_side = "left"
        self.tokenizer.pad_token = self.tokenizer.eos_token
        self.model = (
            AutoModelForCausalLM.from_pretrained(
                model_path,
                local_files_only=True,
                dtype=torch.float32,
                attn_implementation="eager",
                trust_remote_code=False,
            )
            .eval()
            .to(device)
        )

    def sync(self):
        if self.device == "mps":
            self.torch.mps.synchronize()
        elif self.device.startswith("cuda"):
            self.torch.cuda.synchronize()

    def encode(self, text):
        if not text.strip():
            raise ValueError("Prompt must not be empty")
        return self.tokenizer.apply_chat_template(
            [{"role": "user", "content": text}],
            tokenize=True,
            add_generation_prompt=True,
            return_tensors="pt",
            return_dict=True,
        )["input_ids"].to(self.device)

    def _forward(self, ids, cache=None, use_cache=True):
        with self.torch.inference_mode():
            return self.model(input_ids=ids, past_key_values=cache, use_cache=use_cache)

    def run(
        self,
        text,
        max_new_tokens=24,
        use_cache=True,
        chunk_size=None,
        cancel_after=None,
    ):
        if max_new_tokens < 1:
            raise ValueError("Output limit must be positive")
        if chunk_size is not None and chunk_size < 1:
            raise ValueError("Chunk size must be positive")
        self.sync()
        started = time.perf_counter()
        ids = self.encode(text)
        self.sync()
        tokenized = time.perf_counter()
        cache = None
        if chunk_size is not None and not use_cache:
            raise ValueError("Chunking needs a cache")
        for chunk in ids.split(chunk_size or ids.shape[-1], dim=-1):
            result = self._forward(chunk, cache, use_cache)
            cache = result.past_key_values if use_cache else None
        emitted = []
        arrivals = []
        stop = "length"
        context = ids
        eos_ids = self.model.generation_config.eos_token_id
        eos_ids = set(eos_ids if isinstance(eos_ids, list) else [eos_ids])
        for _ in range(max_new_tokens):
            token = result.logits[:, -1].argmax(-1, keepdim=True)
            self.sync()
            token_id = int(token.item())
            arrivals.append(time.perf_counter() - started)
            emitted.append(token_id)
            if token_id in eos_ids:
                stop = "eos"
                break
            if cancel_after is not None and len(emitted) >= cancel_after:
                stop = "cancelled"
                break
            if len(emitted) == max_new_tokens:
                break
            context = self.torch.cat((context, token), dim=-1)
            result = self._forward(token if use_cache else context, cache, use_cache)
            cache = result.past_key_values if use_cache else None
        cache_length = int(cache.get_seq_length()) if cache is not None else 0
        # Release the request-owned cache on every stop, including cancellation.
        del cache, result
        self.sync()
        intervals = [1000 * (b - a) for a, b in zip(arrivals, arrivals[1:])]
        return {
            "prompt": text,
            "prompt_tokens": ids.shape[-1],
            "generated_token_ids": emitted,
            "generated_tokens": len(emitted),
            "text": self.tokenizer.decode(emitted, skip_special_tokens=True),
            "use_cache": use_cache,
            "chunk_size": chunk_size,
            "stop_reason": stop,
            "tokenization_ms": round(1000 * (tokenized - started), 3),
            "ttft_ms": round(arrivals[0] * 1000, 3),
            "tpot_ms": round(statistics.fmean(intervals), 3) if intervals else None,
            "itl_ms": [round(x, 3) for x in intervals],
            "e2e_ms": round(arrivals[-1] * 1000, 3),
            "cache_tokens_before_release": cache_length,
        }

    def batch(self, texts, max_new_tokens=24):
        prompts = [
            self.tokenizer.apply_chat_template(
                [{"role": "user", "content": t}],
                tokenize=False,
                add_generation_prompt=True,
            )
            for t in texts
        ]
        encoded = self.tokenizer(prompts, padding=True, return_tensors="pt").to(
            self.device
        )
        self.sync()
        start = time.perf_counter()
        with self.torch.inference_mode():
            out = self.model.generate(
                **encoded,
                max_new_tokens=max_new_tokens,
                do_sample=False,
                use_cache=True,
            )
        self.sync()
        elapsed = time.perf_counter() - start
        ids = out[:, encoded["input_ids"].shape[-1] :].tolist()
        eos = self.model.generation_config.eos_token_id
        eos = set(eos if isinstance(eos, list) else [eos])
        trimmed = []
        for row in ids:
            n = next((i + 1 for i, x in enumerate(row) if x in eos), len(row))
            trimmed.append(row[:n])
        return {
            "batch_size": len(texts),
            "elapsed_ms": round(elapsed * 1000, 3),
            "output_tokens": sum(map(len, trimmed)),
            "output_tokens_per_s": round(sum(map(len, trimmed)) / elapsed, 3),
            "texts": [
                self.tokenizer.decode(row, skip_special_tokens=True) for row in trimmed
            ],
        }

    def prefix_reuse(self, prefix, suffix):
        # Tokenize the full sequence once: concatenated text tokenization need not equal separate tokenizations.
        full = self.encode(prefix + suffix)
        prefix_length = max(1, full.shape[-1] // 2)
        self.sync()
        start = time.perf_counter()
        cold = self._forward(full)
        self.sync()
        cold_ms = (time.perf_counter() - start) * 1000
        cached = self._forward(full[:, :prefix_length]).past_key_values
        self.sync()
        start = time.perf_counter()
        warm = self._forward(full[:, prefix_length:], cached)
        self.sync()
        warm_ms = (time.perf_counter() - start) * 1000
        error = float((cold.logits[:, -1] - warm.logits[:, -1]).abs().max().item())
        return {
            "total_tokens": full.shape[-1],
            "cached_prefix_tokens": prefix_length,
            "cold_prefill_ms": round(cold_ms, 3),
            "suffix_prefill_ms": round(warm_ms, 3),
            "max_abs_last_logit_diff": error,
            "same_greedy_next_token": int(cold.logits[:, -1].argmax())
            == int(warm.logits[:, -1].argmax()),
        }


def main():
    parser = argparse.ArgumentParser(description=__doc__)
    parser.add_argument("--model-path", required=True)
    parser.add_argument("--device", choices=["cpu", "mps"], default="cpu")
    parser.add_argument("--output", required=True)
    args = parser.parse_args()
    import torch, transformers

    decoder = LocalDecoder(args.model_path, args.device)
    warmup = decoder.run("Explain a cache in one sentence.", max_new_tokens=4)
    short = "Explain why a code assistant should stop generating when its user cancels."
    long = (
        "A retrieval service indexes source code and returns relevant functions. " * 20
    ) + short
    runs = []
    for name, text, options in [
        ("short_cached", short, {}),
        ("long_cached", long, {}),
        ("short_without_cache", short, {"use_cache": False}),
        ("long_chunked", long, {"chunk_size": 64}),
        ("cancelled", short, {"cancel_after": 4}),
    ]:
        samples = [decoder.run(text, **options) for _ in range(3)]
        runs.append(
            {
                "name": name,
                "samples": samples,
                "median_ttft_ms": round(
                    statistics.median(s["ttft_ms"] for s in samples), 3
                ),
                "median_tpot_ms": round(
                    statistics.median(
                        s["tpot_ms"] for s in samples if s["tpot_ms"] is not None
                    ),
                    3,
                ),
            }
        )
    batches = [decoder.batch([short] * n) for n in [1, 2, 4]]
    config = decoder.model.config
    parameters = sum(p.numel() for p in decoder.model.parameters())
    report = {
        "execution_mode": "fresh local inference; no simulated latency",
        "environment": {
            "python": platform.python_version(),
            "platform": platform.platform(),
            "torch": torch.__version__,
            "transformers": transformers.__version__,
            "device": args.device,
        },
        "model": {
            "id": MODEL_ID,
            "revision": MODEL_REVISION,
            "license": "Apache-2.0",
            "dtype": "float32",
            "attention_backend": "eager",
            "parameters": parameters,
            "weight_bytes": sum(
                p.numel() * p.element_size() for p in decoder.model.parameters()
            ),
            "layers": config.num_hidden_layers,
            "kv_heads": config.num_key_value_heads,
            "head_dim": config.hidden_size // config.num_attention_heads,
            "kv_bytes_per_token": 2
            * config.num_hidden_layers
            * config.num_key_value_heads
            * (config.hidden_size // config.num_attention_heads)
            * 4,
        },
        "generation": {
            "strategy": "greedy argmax",
            "max_new_tokens": 24,
            "do_sample": False,
            "warmup_tokens": 4,
            "thinking": "not a configurable reasoning mode in this model",
        },
        "source_sha256": hashlib.sha256(Path(__file__).read_bytes()).hexdigest(),
        "warmup": warmup,
        "runs": runs,
        "batch_sweep": batches,
        "prefix_reuse": decoder.prefix_reuse(long, " Give one practical example."),
        "limits": "Three repeated development prompts per configuration; no held-out quality evaluation, HTTP latency, CUDA profiling, or production load test.",
    }
    Path(args.output).write_text(json.dumps(report, indent=2) + "\n")
    print(
        json.dumps(
            {
                "output": Path(args.output).name,
                "runs": len(runs),
                "batch_sizes": [x["batch_size"] for x in batches],
            },
            indent=2,
        )
    )


if __name__ == "__main__":
    main()
The cached and uncached short-prompt runs use the same prompt and output cap; they differ only in whether the runner keeps the KV cache. Compare their decode medians to see what the cache saves on each token. One small model on one device does not represent a production fleet. The long-prompt comparison changes the input workload, so it answers a different question.
When text is slow to start, check TTFT and prompt length before decode speed. In this run, the longer prompt raised TTFT far more than TPOT.
| Quantity | Recorded value |
|---|---|
| Short prompt TTFT (ms) | 36.399 |
| Short prompt TPOT (ms) | 24.093 |
| Uncached short prompt TPOT (ms) | 39.635 |
| Long prompt TTFT (ms) | 86.29 |
| Chunked long prompt TTFT (ms) | 192.01 |
Inspect the complete local result
{
  "execution_mode": "offline analysis of fresh local inference record",
  "model": {
    "id": "Qwen/Qwen2.5-0.5B-Instruct",
    "revision": "7ae557604adf67be50417f59c2c2f167def9a775",
    "license": "Apache-2.0",
    "dtype": "float32",
    "attention_backend": "eager",
    "parameters": 494032768,
    "weight_bytes": 1976131072,
    "layers": 24,
    "kv_heads": 2,
    "head_dim": 64,
    "kv_bytes_per_token": 24576
  },
  "generation": {
    "strategy": "greedy argmax",
    "max_new_tokens": 24,
    "do_sample": false,
    "warmup_tokens": 4,
    "thinking": "not a configurable reasoning mode in this model"
  },
  "comparisons": {
    "short_cached": {
      "samples": 3,
      "median_ttft_ms": 36.399,
      "median_tpot_ms": 24.093
    },
    "long_cached": {
      "samples": 3,
      "median_ttft_ms": 86.29,
      "median_tpot_ms": 25.288
    },
    "short_without_cache": {
      "samples": 3,
      "median_ttft_ms": 38.318,
      "median_tpot_ms": 39.635
    },
    "long_chunked": {
      "samples": 3,
      "median_ttft_ms": 192.01,
      "median_tpot_ms": 28.243
    },
    "cancelled": {
      "samples": 3,
      "median_ttft_ms": 34.266,
      "median_tpot_ms": 22.446
    }
  },
  "batch_sweep": [
    {
      "batch_size": 1,
      "elapsed_ms": 1144.114,
      "output_tokens": 24,
      "output_tokens_per_s": 20.977,
      "texts": [
        "When a code assistant encounters the user's cancellation of an operation, it is crucial to understand that this action signifies the end"
      ]
    },
    {
      "batch_size": 2,
      "elapsed_ms": 1490.669,
      "output_tokens": 48,
      "output_tokens_per_s": 32.2,
      "texts": [
        "When a code assistant encounters the user's cancellation of an operation, it is crucial to understand that this action signifies the end",
        "When a code assistant encounters the user's cancellation of an operation, it is crucial to understand that this action signifies the end"
      ]
    },
    {
      "batch_size": 4,
      "elapsed_ms": 1243.557,
      "output_tokens": 96,
      "output_tokens_per_s": 77.198,
      "texts": [
        "When a code assistant encounters the user's cancellation of an operation, it is crucial to understand that this action signifies the end",
        "When a code assistant encounters the user's cancellation of an operation, it is crucial to understand that this action signifies the end",
        "When a code assistant encounters the user's cancellation of an operation, it is crucial to understand that this action signifies the end",
        "When a code assistant encounters the user's cancellation of an operation, it is crucial to understand that this action signifies the end"
      ]
    }
  ],
  "prefix_reuse": {
    "total_tokens": 268,
    "cached_prefix_tokens": 134,
    "cold_prefill_ms": 90.296,
    "suffix_prefill_ms": 60.948,
    "max_abs_last_logit_diff": 4.506111145019531e-05,
    "same_greedy_next_token": true
  }
}
Inspect the actual execution record
{
"execution_mode": "fresh local inference; no simulated latency",
"environment": {
"python": "3.12.8",
"platform": "macOS-27.0.1-arm64-arm-64bit",
"torch": "2.14.1",
"transformers": "5.20.2",
"device": "mps"
},
"model": {
"id": "Qwen/Qwen2.5-0.5B-Instruct",
"revision": "7ae557604adf67be50417f59c2c2f167def9a775",
"license": "Apache-2.0",
"dtype": "float32",
"attention_backend": "eager",
"parameters": 494032768,
"weight_bytes": 1976131072,
"layers": 24,
"kv_heads": 2,
"head_dim": 64,
"kv_bytes_per_token": 24576
},
"generation": {
"strategy": "greedy argmax",
"max_new_tokens": 24,
"do_sample": false,
"warmup_tokens": 4,
"thinking": "not a configurable reasoning mode in this model"
},
"source_sha256": "754d9bf81d04694541e53d5c0472f984c9f046886070c33b376ca071c81c8086",
"warmup": {
"prompt": "Explain a cache in one sentence.",
"prompt_tokens": 37,
"generated_token_ids": [
32,
6500,
374,
264
],
"generated_tokens": 4,
"text": "A cache is a",
"use_cache": true,
"chunk_size": null,
"stop_reason": "length",
"tokenization_ms": 6.358,
"ttft_ms": 138.267,
"tpot_ms": 25.619,
"itl_ms": [
27.98,
23.916,
24.96
],
"e2e_ms": 215.123,
"cache_tokens_before_release": 40
},
"runs": [
{
"name": "short_cached",
"samples": [
{
"prompt": "Explain why a code assistant should stop generating when its user cancels.",
"prompt_tokens": 44,
"generated_token_ids": [
4498,
264,
2038,
17847,
33906,
264,
1196,
879,
702,
33446,
862,
1681,
11,
432,
374,
16587,
311,
3535,
279,
2266,
323,
279,
6993,
315
],
"generated_tokens": 24,
"text": "When a code assistant encounters a user who has canceled their request, it is crucial to understand the context and the nature of",
"use_cache": true,
"chunk_size": null,
"stop_reason": "length",
"tokenization_ms": 0.42,
"ttft_ms": 36.971,
"tpot_ms": 37.841,
"itl_ms": [
24.717,
24.26,
24.26,
23.673,
23.945,
24.013,
23.746,
23.935,
24.656,
24.232,
24.202,
23.957,
24.223,
24.584,
24.632,
24.522,
25.532,
25.876,
25.605,
201.281,
148.208,
27.729,
28.559
],
"e2e_ms": 907.318,
"cache_tokens_before_release": 67
},
{
"prompt": "Explain why a code assistant should stop generating when its user cancels.",
"prompt_tokens": 44,
"generated_token_ids": [
4498,
264,
2038,
17847,
33906,
264,
1196,
879,
702,
33446,
862,
1681,
11,
432,
374,
16587,
311,
3535,
279,
2266,
323,
279,
6993,
315
],
"generated_tokens": 24,
"text": "When a code assistant encounters a user who has canceled their request, it is crucial to understand the context and the nature of",
"use_cache": true,
"chunk_size": null,
"stop_reason": "length",
"tokenization_ms": 0.508,
"ttft_ms": 36.399,
"tpot_ms": 24.093,
"itl_ms": [
24.36,
24.582,
23.627,
23.961,
24.925,
24.601,
24.032,
24.172,
24.462,
24.122,
24.799,
24.095,
23.782,
23.391,
23.578,
24.265,
23.98,
24.264,
23.391,
22.59,
24.304,
24.778,
24.084
],
"e2e_ms": 590.543,
"cache_tokens_before_release": 67
},
{
"prompt": "Explain why a code assistant should stop generating when its user cancels.",
"prompt_tokens": 44,
"generated_token_ids": [
4498,
264,
2038,
17847,
33906,
264,
1196,
879,
702,
33446,
862,
1681,
11,
432,
374,
16587,
311,
3535,
279,
2266,
323,
279,
6993,
315
],
"generated_tokens": 24,
"text": "When a code assistant encounters a user who has canceled their request, it is crucial to understand the context and the nature of",
"use_cache": true,
"chunk_size": null,
"stop_reason": "length",
"tokenization_ms": 0.538,
"ttft_ms": 36.34,
"tpot_ms": 23.944,
"itl_ms": [
23.965,
23.525,
23.857,
23.826,
22.808,
23.116,
22.953,
23.944,
23.659,
23.274,
23.324,
23.85,
23.623,
24.623,
24.886,
25.403,
24.198,
24.893,
24.711,
23.619,
24.964,
24.146,
23.548
],
"e2e_ms": 587.054,
"cache_tokens_before_release": 67
}
],
"median_ttft_ms": 36.399,
"median_tpot_ms": 24.093
},
{
"name": "long_cached",
"samples": [
{
"prompt": "A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. Explain why a code assistant should stop generating when its user cancels.",
"prompt_tokens": 263,
"generated_token_ids": [
4498,
264,
2038,
17847,
33906,
264,
1196,
879,
702,
33446,
279,
10435,
11,
432,
594,
2989,
311,
3535,
279,
2266,
323,
279,
7966,
4815
],
"generated_tokens": 24,
"text": "When a code assistant encounters a user who has canceled the conversation, it's important to understand the context and the reasons behind",
"use_cache": true,
"chunk_size": null,
"stop_reason": "length",
"tokenization_ms": 0.758,
"ttft_ms": 273.572,
"tpot_ms": 26.82,
"itl_ms": [
27.356,
27.6,
26.837,
26.249,
27.147,
27.567,
27.574,
26.044,
26.353,
26.533,
26.771,
26.266,
25.951,
26.33,
26.194,
26.868,
26.187,
27.931,
27.892,
26.783,
27.818,
25.98,
26.633
],
"e2e_ms": 890.437,
"cache_tokens_before_release": 286
},
{
"prompt": "A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. Explain why a code assistant should stop generating when its user cancels.",
"prompt_tokens": 263,
"generated_token_ids": [
4498,
264,
2038,
17847,
33906,
264,
1196,
879,
702,
33446,
279,
10435,
11,
432,
594,
2989,
311,
3535,
279,
2266,
323,
279,
7966,
4815
],
"generated_tokens": 24,
"text": "When a code assistant encounters a user who has canceled the conversation, it's important to understand the context and the reasons behind",
"use_cache": true,
"chunk_size": null,
"stop_reason": "length",
"tokenization_ms": 0.85,
"ttft_ms": 86.29,
"tpot_ms": 25.288,
"itl_ms": [
26.506,
25.52,
26.769,
24.864,
25.298,
26.576,
25.433,
23.891,
23.809,
23.687,
26.404,
26.394,
25.43,
25.29,
25.059,
24.146,
24.421,
24.663,
26.637,
25.673,
25.497,
24.925,
24.726
],
"e2e_ms": 667.908,
"cache_tokens_before_release": 286
},
{
"prompt": "A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. Explain why a code assistant should stop generating when its user cancels.",
"prompt_tokens": 263,
"generated_token_ids": [
4498,
264,
2038,
17847,
33906,
264,
1196,
879,
702,
33446,
279,
10435,
11,
432,
594,
2989,
311,
3535,
279,
2266,
323,
279,
7966,
4815
],
"generated_tokens": 24,
"text": "When a code assistant encounters a user who has canceled the conversation, it's important to understand the context and the reasons behind",
"use_cache": true,
"chunk_size": null,
"stop_reason": "length",
"tokenization_ms": 0.694,
"ttft_ms": 84.662,
"tpot_ms": 24.334,
"itl_ms": [
25.428,
25.259,
24.846,
24.946,
25.267,
23.982,
24.173,
24.283,
24.333,
23.722,
23.755,
23.511,
24.927,
24.42,
24.321,
24.326,
24.096,
24.343,
23.912,
24.211,
24.209,
23.855,
23.554
],
"e2e_ms": 644.34,
"cache_tokens_before_release": 286
}
],
"median_ttft_ms": 86.29,
"median_tpot_ms": 25.288
},
{
"name": "short_without_cache",
"samples": [
{
"prompt": "Explain why a code assistant should stop generating when its user cancels.",
"prompt_tokens": 44,
"generated_token_ids": [
4498,
264,
2038,
17847,
33906,
264,
1196,
879,
702,
33446,
862,
1681,
11,
432,
374,
16587,
311,
3535,
279,
2266,
323,
279,
6993,
315
],
"generated_tokens": 24,
"text": "When a code assistant encounters a user who has canceled their request, it is crucial to understand the context and the nature of",
"use_cache": false,
"chunk_size": null,
"stop_reason": "length",
"tokenization_ms": 0.37,
"ttft_ms": 66.297,
"tpot_ms": 67.008,
"itl_ms": [
79.186,
134.713,
39.694,
226.116,
201.879,
41.316,
41.58,
41.005,
40.472,
41.45,
81.137,
42.528,
40.705,
40.632,
41.435,
41.415,
42.948,
40.251,
41.818,
41.779,
109.786,
44.586,
44.763
],
"e2e_ms": 1607.491,
"cache_tokens_before_release": 0
},
{
"prompt": "Explain why a code assistant should stop generating when its user cancels.",
"prompt_tokens": 44,
"generated_token_ids": [
4498,
264,
2038,
17847,
33906,
264,
1196,
879,
702,
33446,
862,
1681,
11,
432,
374,
16587,
311,
3535,
279,
2266,
323,
279,
6993,
315
],
"generated_tokens": 24,
"text": "When a code assistant encounters a user who has canceled their request, it is crucial to understand the context and the nature of",
"use_cache": false,
"chunk_size": null,
"stop_reason": "length",
"tokenization_ms": 0.388,
"ttft_ms": 37.483,
"tpot_ms": 39.405,
"itl_ms": [
36.29,
37.237,
37.341,
39.518,
38.716,
39.582,
38.704,
39.39,
39.481,
39.121,
39.194,
40.456,
40.368,
39.749,
40.942,
39.908,
39.032,
38.143,
39.892,
36.976,
41.664,
41.7,
42.915
],
"e2e_ms": 943.802,
"cache_tokens_before_release": 0
},
{
"prompt": "Explain why a code assistant should stop generating when its user cancels.",
"prompt_tokens": 44,
"generated_token_ids": [
4498,
264,
2038,
17847,
33906,
264,
1196,
879,
702,
33446,
862,
1681,
11,
432,
374,
16587,
311,
3535,
279,
2266,
323,
279,
6993,
315
],
"generated_tokens": 24,
"text": "When a code assistant encounters a user who has canceled their request, it is crucial to understand the context and the nature of",
"use_cache": false,
"chunk_size": null,
"stop_reason": "length",
"tokenization_ms": 0.417,
"ttft_ms": 38.318,
"tpot_ms": 39.635,
"itl_ms": [
36.313,
37.162,
37.48,
40.273,
39.284,
39.079,
39.382,
38.926,
40.223,
39.338,
39.432,
39.342,
39.309,
39.563,
40.44,
40.655,
40.428,
39.193,
40.016,
38.449,
41.942,
42.91,
42.457
],
"e2e_ms": 949.915,
"cache_tokens_before_release": 0
}
],
"median_ttft_ms": 38.318,
"median_tpot_ms": 39.635
},
{
"name": "long_chunked",
"samples": [
{
"prompt": "A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. Explain why a code assistant should stop generating when its user cancels.",
"prompt_tokens": 263,
"generated_token_ids": [
4498,
264,
2038,
17847,
33906,
264,
1196,
879,
702,
33446,
279,
10435,
11,
432,
594,
2989,
311,
3535,
279,
2266,
323,
279,
7966,
4815
],
"generated_tokens": 24,
"text": "When a code assistant encounters a user who has canceled the conversation, it's important to understand the context and the reasons behind",
"use_cache": true,
"chunk_size": 64,
"stop_reason": "length",
"tokenization_ms": 0.835,
"ttft_ms": 702.895,
"tpot_ms": 28.833,
"itl_ms": [
38.292,
66.814,
41.939,
32.362,
26.243,
25.407,
24.949,
25.175,
26.761,
25.854,
25.866,
25.026,
25.473,
25.808,
25.566,
26.479,
25.683,
24.899,
25.496,
24.559,
24.987,
24.635,
24.89
],
"e2e_ms": 1366.057,
"cache_tokens_before_release": 286
},
{
"prompt": "A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. Explain why a code assistant should stop generating when its user cancels.",
"prompt_tokens": 263,
"generated_token_ids": [
4498,
264,
2038,
17847,
33906,
264,
1196,
879,
702,
33446,
279,
10435,
11,
432,
594,
2989,
311,
3535,
279,
2266,
323,
279,
7966,
4815
],
"generated_tokens": 24,
"text": "When a code assistant encounters a user who has canceled the conversation, it's important to understand the context and the reasons behind",
"use_cache": true,
"chunk_size": 64,
"stop_reason": "length",
"tokenization_ms": 0.797,
"ttft_ms": 180.806,
"tpot_ms": 28.243,
"itl_ms": [
24.767,
25.971,
28.707,
28.913,
29.586,
32.806,
33.812,
32.961,
28.86,
30.909,
27.018,
25.968,
25.662,
26.752,
26.08,
25.695,
26.85,
25.259,
26.738,
29.582,
31.276,
28.427,
26.987
],
"e2e_ms": 830.391,
"cache_tokens_before_release": 286
},
{
"prompt": "A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. A retrieval service indexes source code and returns relevant functions. Explain why a code assistant should stop generating when its user cancels.",
"prompt_tokens": 263,
"generated_token_ids": [
4498,
264,
2038,
17847,
33906,
264,
1196,
879,
702,
33446,
279,
10435,
11,
432,
594,
2989,
311,
3535,
279,
2266,
323,
279,
7966,
4815
],
"generated_tokens": 24,
"text": "When a code assistant encounters a user who has canceled the conversation, it's important to understand the context and the reasons behind",
"use_cache": true,
"chunk_size": 64,
"stop_reason": "length",
"tokenization_ms": 0.763,
"ttft_ms": 192.01,
"tpot_ms": 25.814,
"itl_ms": [
25.66,
25.885,
25.866,
26.904,
26.668,
26.756,
26.449,
27.375,
25.687,
25.242,
25.962,
25.179,
24.328,
24.858,
24.397,
24.939,
24.364,
24.276,
26.038,
27.134,
27.045,
26.886,
25.831
],
"e2e_ms": 785.739,
"cache_tokens_before_release": 286
}
],
"median_ttft_ms": 192.01,
"median_tpot_ms": 28.243
},
{
"name": "cancelled",
"samples": [
{
"prompt": "Explain why a code assistant should stop generating when its user cancels.",
"prompt_tokens": 44,
"generated_token_ids": [
4498,
264,
2038,
17847
],
"generated_tokens": 4,
"text": "When a code assistant",
"use_cache": true,
"chunk_size": null,
"stop_reason": "cancelled",
"tokenization_ms": 0.454,
"ttft_ms": 39.63,
"tpot_ms": 27.403,
"itl_ms": [
28.558,
28.742,
24.91
],
"e2e_ms": 121.84,
"cache_tokens_before_release": 47
},
{
"prompt": "Explain why a code assistant should stop generating when its user cancels.",
"prompt_tokens": 44,
"generated_token_ids": [
4498,
264,
2038,
17847
],
"generated_tokens": 4,
"text": "When a code assistant",
"use_cache": true,
"chunk_size": null,
"stop_reason": "cancelled",
"tokenization_ms": 0.387,
"ttft_ms": 33.383,
"tpot_ms": 22.446,
"itl_ms": [
21.98,
21.693,
23.664
],
"e2e_ms": 100.721,
"cache_tokens_before_release": 47
},
{
"prompt": "Explain why a code assistant should stop generating when its user cancels.",
"prompt_tokens": 44,
"generated_token_ids": [
4498,
264,
2038,
17847
],
"generated_tokens": 4,
"text": "When a code assistant",
"use_cache": true,
"chunk_size": null,
"stop_reason": "cancelled",
"tokenization_ms": 0.456,
"ttft_ms": 34.266,
"tpot_ms": 20.906,
"itl_ms": [
20.964,
21.509,
20.245
],
"e2e_ms": 96.985,
"cache_tokens_before_release": 47
}
],
"median_ttft_ms": 34.266,
"median_tpot_ms": 22.446
}
],
"batch_sweep": [
{
"batch_size": 1,
"elapsed_ms": 1144.114,
"output_tokens": 24,
"output_tokens_per_s": 20.977,
"texts": [
"When a code assistant encounters the user's cancellation of an operation, it is crucial to understand that this action signifies the end"
]
},
{
"batch_size": 2,
"elapsed_ms": 1490.669,
"output_tokens": 48,
"output_tokens_per_s": 32.2,
"texts": [
"When a code assistant encounters the user's cancellation of an operation, it is crucial to understand that this action signifies the end",
"When a code assistant encounters the user's cancellation of an operation, it is crucial to understand that this action signifies the end"
]
},
{
"batch_size": 4,
"elapsed_ms": 1243.557,
"output_tokens": 96,
"output_tokens_per_s": 77.198,
"texts": [
"When a code assistant encounters the user's cancellation of an operation, it is crucial to understand that this action signifies the end",
"When a code assistant encounters the user's cancellation of an operation, it is crucial to understand that this action signifies the end",
"When a code assistant encounters the user's cancellation of an operation, it is crucial to understand that this action signifies the end",
"When a code assistant encounters the user's cancellation of an operation, it is crucial to understand that this action signifies the end"
]
}
],
"prefix_reuse": {
"total_tokens": 268,
"cached_prefix_tokens": 134,
"cold_prefill_ms": 90.296,
"suffix_prefill_ms": 60.948,
"max_abs_last_logit_diff": 4.506111145019531e-05,
"same_greedy_next_token": true
},
"limits": "Three repeated development prompts per configuration; no held-out quality evaluation, HTTP latency, CUDA profiling, or production load test."
}

This image is a report rendered from the saved lab.py result, not a new inference run. Open the full-resolution report or read the raw result.
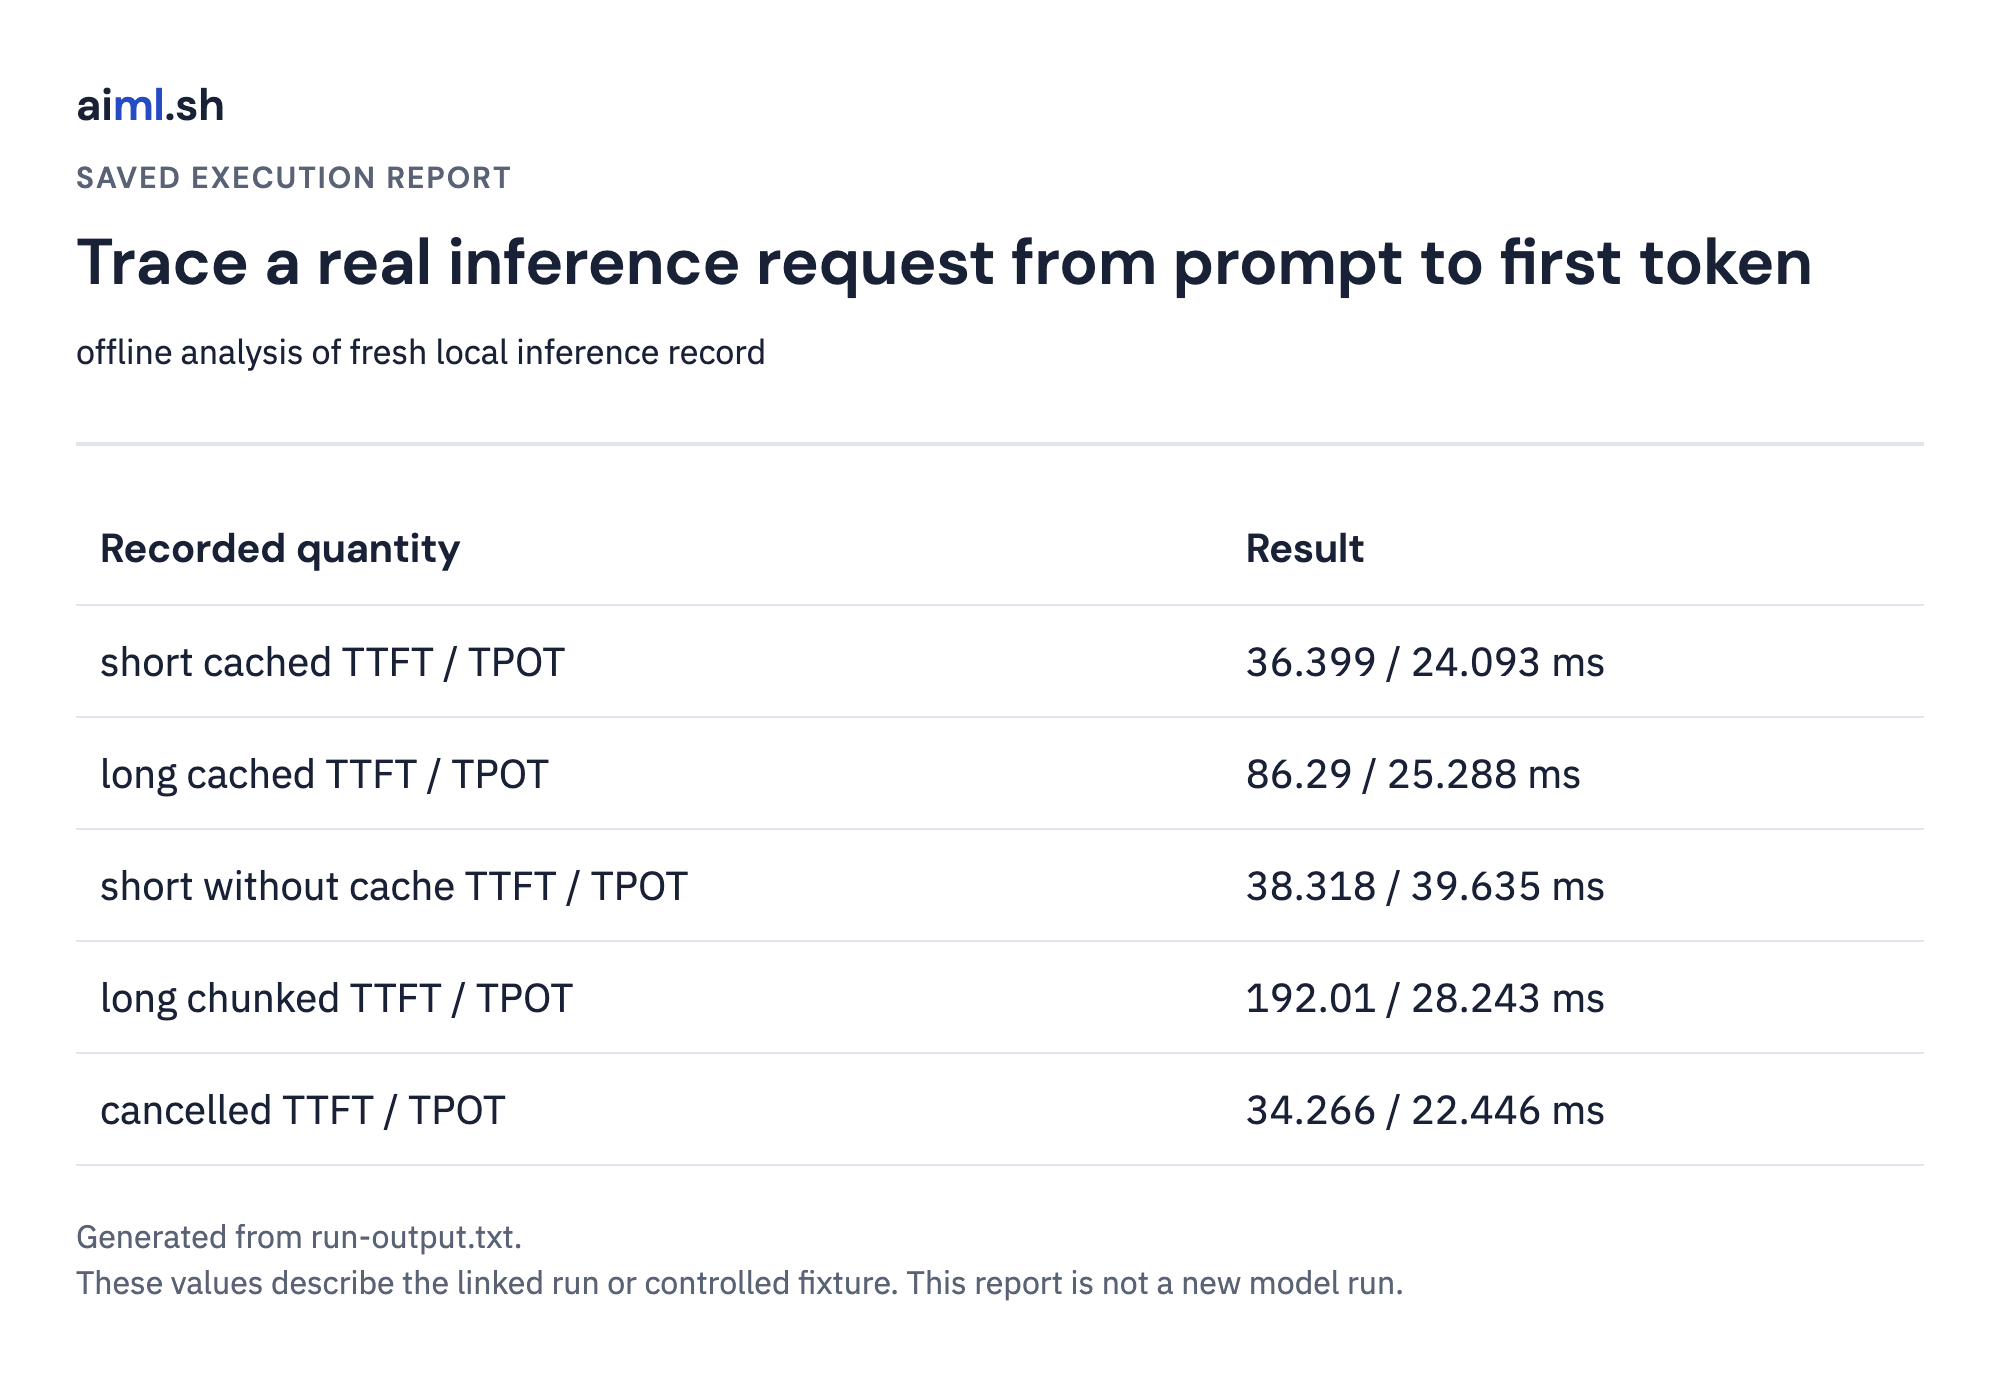
Separate first-token delay from decode pace
A longer prompt adds prefill work and cache state. Keeping KV state saves repeated computation but consumes memory for every active request. Turning off the cache changes both compute and memory allocation; the lab turns it off only to measure what the cache saves. The runner synchronizes the device before each timestamp, so each timestamp falls after the work it measures. That synchronization can also slow the run.
Measure chunked prefill before you adopt it. In this run, which sent one request at a time, the chunked long prompt (64-token chunks) had a higher TTFT than the same prompt prefilled in one pass.
Missing token intervals. A response with missing decode intervals is rejected instead of silently averaging an incomplete trace.
Invalid token timing. An end timestamp before the first token is rejected. Negative and nonfinite timing values also fail validation.
Token count mismatch. A declared output count that differs from the saved token IDs is rejected. A valid one-token response has no TPOT.
Read the executable checks
import unittest
from lab import summarize


class TraceTests(unittest.TestCase):
    def sample(self):
        return {
            "generated_tokens": 3,
            "generated_token_ids": [4, 5, 6],
            "ttft_ms": 10,
            "e2e_ms": 30,
            "itl_ms": [8, 12],
        }

    def test_average_decode_interval_excludes_prefill(self):
        result = summarize([self.sample()])
        self.assertEqual(result["median_ttft_ms"], 10)
        self.assertEqual(result["median_tpot_ms"], 10)

    def test_rejects_missing_token_interval(self):
        sample = self.sample()
        sample["itl_ms"] = [8]
        with self.assertRaisesRegex(ValueError, "Missing token intervals"):
            summarize([sample])

    def test_rejects_end_before_first_token(self):
        sample = self.sample()
        sample["e2e_ms"] = 2
        with self.assertRaisesRegex(ValueError, "Invalid token timing"):
            summarize([sample])

    def test_rejects_inconsistent_generated_count(self):
        sample = self.sample()
        sample["generated_tokens"] = 2
        with self.assertRaisesRegex(ValueError, "Token count mismatch"):
            summarize([sample])


class TraceBoundaryTests(unittest.TestCase):
    def test_one_token_has_no_tpot(self):
        self.assertIsNone(
            summarize(
                [
                    {
                        "generated_tokens": 1,
                        "generated_token_ids": [4],
                        "ttft_ms": 10,
                        "e2e_ms": 10,
                        "itl_ms": [],
                    }
                ]
            )["median_tpot_ms"]
        )

    def test_negative_and_nonfinite_intervals_are_rejected(self):
        for interval in [-1, float("nan"), float("inf")]:
            with self.assertRaises(ValueError):
                summarize(
                    [
                        {
                            "generated_tokens": 2,
                            "generated_token_ids": [4, 5],
                            "ttft_ms": 10,
                            "e2e_ms": 20,
                            "itl_ms": [interval],
                        }
                    ]
                )


if __name__ == "__main__":
    unittest.main()


class GuardBoundaryTests(unittest.TestCase):
    def test_rejects_invalid_boundary_inputs_with_specific_reason(self):
        import lab
        cases = [('summarize([])', 'At least one'), ('summarize([dict(generated_tokens=1,generated_token_ids=[1],ttft_ms=float("nan"),e2e_ms=0,itl_ms=[])])', 'Timing values'), ('summarize([dict(generated_tokens=2,generated_token_ids=[1,2],ttft_ms=10,e2e_ms=20,itl_ms=[9])])', 'Intervals do not')]
        for code, reason in cases:
            with self.subTest(code=code):
                with self.assertRaisesRegex((ValueError, MemoryError, KeyError, RuntimeError), reason):
                    exec(code, vars(lab).copy())
The live runner’s prefix_reuse record compares the final-position logits of a full prefill with those of a cached prefix plus the remaining tokens. batch_sweep records separate static-batch calls to generate(). Those calls use a different loop from the stage trace, so do not compare their timings with the trace as if only batch size changed.
Run fresh local inference
The optional download below is about 1 GB and uses the official model at its pinned revision. Use --device cpu on a CPU host. The recorded run used the Metal backend, not CUDA. The model card identifies the Apache-2.0 license.
python3 -m venv .venv
.venv/bin/python -m pip install -r requirements-live.txt
.venv/bin/python download_model.py --destination ./model
.venv/bin/python live_inference.py --model-path ./model --device mps --output new-live-run.json
Compare your result
Compare the cached and uncached runs on the same short prompt. Then compare the two prompt lengths. Explain why TTFT and TPOT should be reported separately; use the saved token IDs and intervals to support your answer.
Read the explanation
TTFT and decode intervals have different boundaries. Locate the delay before changing the system.
Measure at a consistent boundary
Use the same measurement boundary, prompt, generation settings, warmup policy, and output length when comparing changes. Keep cold start separate from warm request latency. Repeat each configuration and report the median: in the recorded run, the first sample had the highest TTFT in every configuration. A plausible generated explanation is not a task-quality evaluation.
References
Sources checked October 24, 2026. Runtime-specific commands and results apply to the recorded versions; linked rolling documentation can change. The application scenarios are teaching examples, not reports of a real production incident.